

Pathways Language Mannequin 2 (PaLM 2) is a big language mannequin (LLM) developed by Google. It was introduced in Might 2023 as a successor to the PaLM mannequin, which was initially launched in January 2022. The PaLM 2 mannequin is skilled on an enormous information set of textual content and code and might carry out a variety of duties, comparable to phrase completion, code completion, query answering, summarization, and sentiment evaluation.
PaLM 2 is a basis mannequin that’s core to Google’s platform for generative AI. PaLM 2 powers Bard, Google’s AI chatbot that competes with OpenAI’s ChatGPT, and Duet AI, Google’s AI assistant framework that’s being built-in into merchandise comparable to Google Workspace and Google Cloud.
Google is making the PaLM API out there inside the Vertex AI platform and as a standalone API endpoint. Builders can entry the Vertex AI PaLM API at present, whereas the standalone endpoint is on the market solely by way of the Trusted Testers program.
Up and working with Python and Vertex AI
Assuming you’re a subscriber to Google Cloud, this tutorial walks you thru the steps of exploring the PaLM API out there within the Vertex AI platform. Please notice that the service is in preview, and the API might change sooner or later.
Let’s begin by making a Python digital atmosphere for our experiment.
python3 -m venv venv
supply venv/bin/activate
Then we set up the Python module to entry the Google Vertex AI platform.
pip set up google-cloud-aiplatform
We may also set up Jupyter Pocket book, which we’ll use as our growth atmosphere.
pip set up jupyter
The library, vertexai.preview.language_models, has a number of courses together with ChatModel, TextEmbedding, and TextGenerationModel. For this tutorial, we’ll concentrate on the TextGenerationModel, the place PaLM 2 will assist us generate a weblog put up primarily based on the enter immediate.
As a primary step, import the precise class from the module.
Import vertexai.preview.language_models import TextGenerationModel
We’ll then initialize the item primarily based on the pre-trained mannequin, text-bison@001, which is optimized for producing textual content.
mannequin = TextGenerationModel.from_pretrained("text-bison@001")
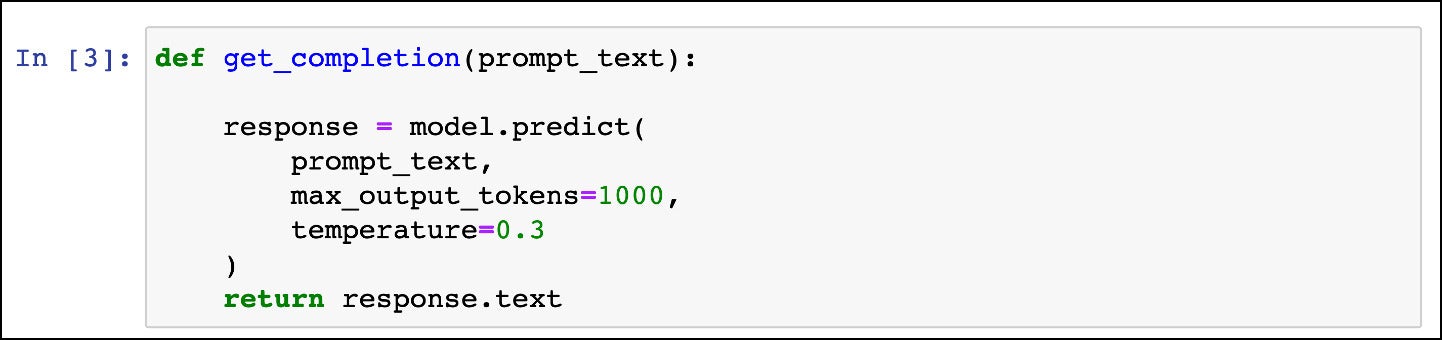
The subsequent step is to outline a operate that accepts the immediate as an enter and returns the response generated by the mannequin as output.
def get_completion(prompt_text):
    response = mannequin.predict(
        prompt_text,
        max_output_tokens=1000,
        temperature=0.3
    )
    return response.textual content
 IDG
The tactic, predict, accepts the immediate, the variety of tokens, and temperature as parameters. Let’s perceive these parameters higher.
Textual content era mannequin parameters
Whereas we submit prompts to the PaLM API within the type of textual content strings, the API converts these strings into chunks of that means known as tokens. A token is roughly 4 characters. 100 tokens correspond to roughly 60 to 80 phrases. If we would like the mannequin’s output to be inside 500 phrases, it’s secure to set the max_output_tokens worth to 1000. The utmost worth supported by the mannequin is 1024. If we didn’t embody this parameter, the worth would default to 64.
The subsequent parameter, temperature, specifies the creativity of the mannequin. This setting controls how random the token choice will likely be. Decrease temperatures are higher for prompts that want a selected and fewer artistic response, whereas greater temperatures can lead to extra various and artistic solutions. The temperature worth might be between 0 and 1. Since we would like a little bit of creativity, we set this to 0.3.
Temperature too is an non-compulsory parameter, the default worth for which varies by mannequin. Two different non-compulsory parameters, top_k and top_p, help you change how the mannequin selects tokens for output, however we’ll skip them right here.
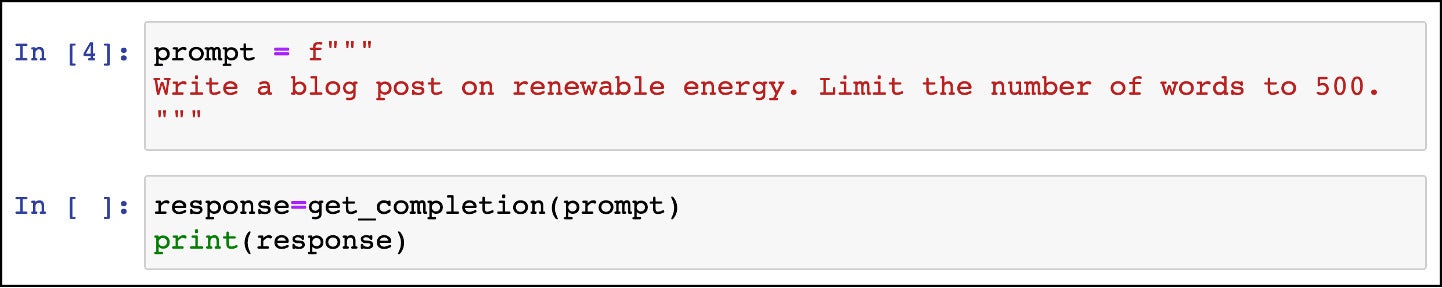
With the tactic in place, let’s assemble the immediate.
immediate = f"""
Write a weblog put up on renewable power. Restrict the variety of phrases to 500.
"""
Invoke the tactic by passing the immediate.
response=get_completion(immediate)
print(response)
 IDG
It is best to see a well-written weblog put up generated by PaLM.
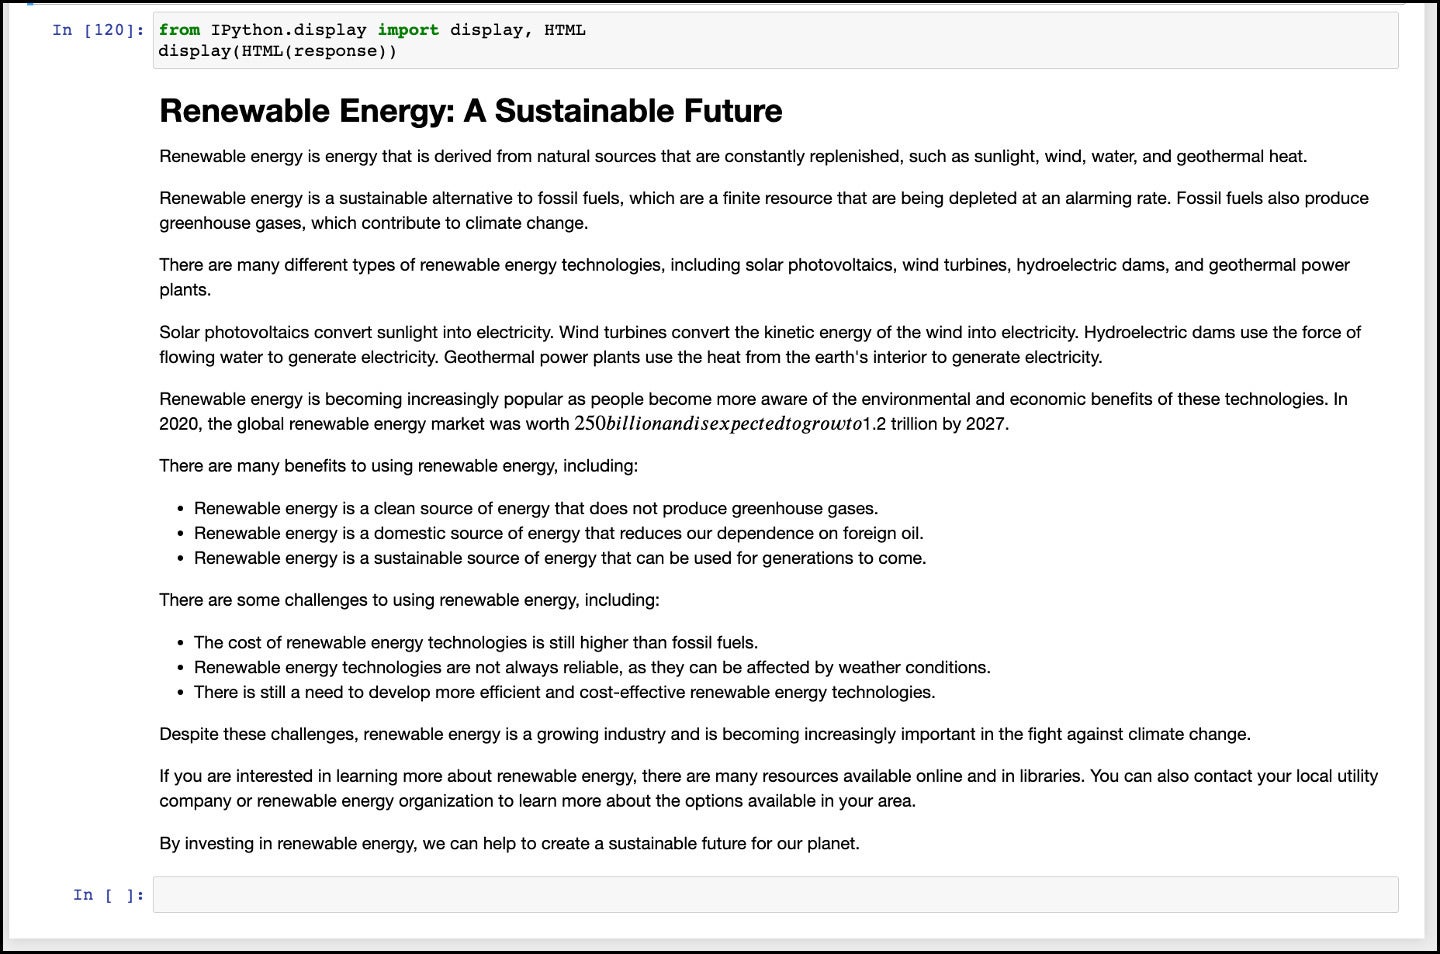
Let’s make this life like by asking PaLM to generate the content material formatted in HTML. For that, we have to modify the immediate.
immediate = f"""
Write a weblog put up on renewable power. Restrict the variety of phrases to 500.
Format the output in HTML.
"""
To print the output in HTML format, we will use the built-in widgets of the Jupyter Pocket book.
from IPython.show import show, HTML
show(HTML(response))
Now you can see the weblog put up formatted in HTML.
 IDG
Under is the whole code to your reference.
from vertexai.preview.language_models import TextGenerationModel
mannequin = TextGenerationModel.from_pretrained("text-bison@001")
def get_completion(prompt_text):
    response = mannequin.predict(
        prompt_text,
        max_output_tokens=1000,
        temperature=0.3
    )
    return response.textual content
immediate = f"""
Write a weblog put up on renewable power. Restrict the variety of phrases to 500.
Format the output in HTML.
"""
response=get_completion(immediate)
print(response)
from IPython.show import show, HTML
show(HTML(response))
In only a few strains of code, we have now invoked the PaLM 2 LLM to generate a weblog put up. In upcoming tutorials, we’ll discover different capabilities of the mannequin together with code completion, chat, and phrase embeddings. Keep tuned.
Copyright © 2023 IDG Communications, Inc.

