


I evaluated 20+ tools to find the 9 best voice recognition software for 2026. These include Deepgram, Google Cloud Speech-to-Text, Krisp, AssemblyAI – Speech to Text API, Otter.ai, IBM Watson Speech to Text, OpenAI Whisper, Azure AI Speech, and Amazon Transcribe.
Whenever I am driving across the city, I always resort to voice recognition-based GPS navigation to get directions right. Just like me, more consumers have switched to conversational voice agents or virtual assistants like Siri or Alexa to vocalize their tasks and improve productivity. But what goes into the making of these?
As the world becomes more inclusive and artificial intelligence reaches further into daily life, people will prefer more voice-friendly tools and services to make efficiency the new norm. This intrigued me enough to analyze 20+ best voice recognition tools and see how the companies at the forefront of building them solve challenges like voice data management, accent issues, multi-language inputs, and lack of data privacy while designing new voice recognition products.
Out of all tools, I compare the nine best voice recognition software that stood out for their accuracy and AI features, based on G2 Data and user feedback. Let’s get into it.
9 best voice recognition software to try out in 2026: Top picks
-
Deepgram: Best for developers needing fast, accurate transcription APIs
Transcribes live and pre-recorded audio through low-latency APIs and custom-trained models. (starts from $0.0065/minute)
-
Google Cloud Speech-to-Text: Best for teams on Google Cloud scaling multilingual, real-time transcription
Converts audio to text in real time across 100-plus languages, integrated with Google Cloud’s data and AI services. (starts from $0.024/minute)
-
Krisp: Best for remote teams removing background noise from live calls
Cancels background noise, transcribes meetings, and adds summaries on top of any conferencing or dialer tool. (starts from $8/user/month, billed annually)
-
AssemblyAI – Speech to Text API: Best for product teams adding AI audio intelligence like summarization and sentiment
Provides built-in models for summarization, sentiment, speaker detection, and LLM-based audio analysis. (starts from $0.21/hour)
-
Otter.ai: Best for professionals capturing and searching automated meeting notes
Records, transcribes, and summarizes meetings in real time, with speaker identification and searchable notes for business and education users. ($4.17/user/month, billed annually)
-
IBM Watson Speech-to-Text: Best for deep learning and speech recognition
Transcribes audio with custom language models and offers accurate speech-to-text capabilities. (starts from $0.02/minute)
-
OpenAI Whisper: Best for builders who want free, open-source multilingual model
Transcribes and translates audio across dozens of languages, self-hosted or via API. (Open-source; API starts from $0.017/minute)
-
Azure AI Speech: Best for Microsoft-stack enterprises needing customizable speech and voice
Provides speech-to-text, text-to-speech, and translation with custom models and enterprise compliance inside the Microsoft Azure ecosystem. (starts from $1/hour)
-
Amazon Transcribe: Best for AWS teams adding transcription and call analytics to pipelines
Converts speech to text within AWS, with call analytics, medical transcription, and automatic content redaction. (starts from $0.006/minute)
*These voice recognition tools are top-rated in their category, according to G2’s Summer 2026 Grid Reports. I’ve also included their monthly pricing to facilitate easier comparisons for you.
According to Mordor Intelligence, the global voice recognition market reached USD 22.51 billion in 2025 and is forecasted to advance at a 22.38% CAGR to attain USD 61.78 billion by 2031.
9 best voice recognition software that I analyzed
When I analyzed this category, I treated it as a productivity layer buyers pay for. As I worked through the user feedback, one hurdle came up more than any other: storing and interpreting voice data across multiple languages. Accents, code-switching, and noisy rooms are where most tools still stumble, and that gap is what separates a clean demo from something a team can rely on daily.
In that context, large language model integration changes the math. LLMs provide the capacity to interpret audio and video text, improve the operational efficiency of the algorithm, and fine-tune the vocabulary of the software algorithm. Integrating these large language models with the main voice interface improves voice dictation and reduces the noisy backgrounds from voice inputs to type accurate sentences. How well a tool pairs its speech model with a language model increasingly sorts the leaders from the rest.
I focused on how each tool handles language inclusivity and voice interpretation for day-to-day operations. To shortlist the nine below, I weighed a few factors.
How did I find and evaluate the best voice recognition software?
I spent weeks evaluating voice recognition software and shortlisted the best based on market parameters, pros and cons, latest features, and recent user reviews.
To build a shortlist, I started with G2’s Voice Recognition Software Grid Report, reading how they score on usability, scalability, and core features, alongside satisfaction, customer segment, and time-to-go-live.
I also included AI in my research process to sift through distinct software updates, reviewer likes and dislikes, and common usage patterns, so the opinions here reflect patterns users consistently report.
All product screenshots in this article come from official vendor G2 pages and publicly available materials.
My take on what makes a voice recognition tool worth it
What I weighed comes down to one question: can the tool turn messy, real-world speech into accurate, usable text fast enough to act on? That matters whether a business is tracking warehouse operations, a person relies on an assistive device, or a customer just wants a faster answer from support.
As I compared the nine tools across G2 reviews and G2 Data, these are the factors that separated them.
- Accuracy and speech recognition capabilities: The first thing I looked for was how accurately the software interprets and transcribes human speech. I also checked whether these solutions can effectively handle diverse input languages, accents, dialects, and background noise. The key was to interpret voice dictation and convert it into real-time action without semantic word gaps.
- Natural language processing and context awareness: I also shortlisted tools that derived correlations from voice input and broke down the contextual significance of words with natural language processing. Not only did I want this software to process user input, but also sense intent, drive semantic relationships, and draw a context to respond cohesively and improve user satisfaction.
- Real-time processing and latency: As voice recognition devices are chosen for speed and agility of task completion, they cannot suggest solutions that offer slow processing turnaround or response latency. As the goal of a voice recognition system is to automate voice content, there should be minimal latency or bottlenecks during instant response generation. If there is a notable delay, like in conversational agents or virtual assistants, it would get really frustrating.
- Customization and integration: I double-checked technical configuration and integration capabilities to ensure these solutions fit into your AI/ML development workflows. As some tools are flexible and scalable while others offer a defined tech stack, I looked for customizable solutions that can be plugged into organizational enterprise resource planning (ERP) workflows. Businesses that have different levels of AI maturity can explore and evaluate these voice recognition tools to automate content generation and delivery, and manage large databases with ease.
- Security and data privacy: Since voice data is sensitive, having high standards for data security, GDPR compliance, encryption, and anti-ransomware features was an imperative point in my evaluation. Having a dedicated security architecture during large-scale data transfers or data exchange with new software users would prevent any risk of cyber threats, DDOS attacks, or unethical hacking.
- Multilingual and multimodal support: While voice recognition tools haven’t quite achieved that flair with major regional languages, these tools still support major dialects and languages spoken globally and interpret user voice orders in any language with the exact action or service. I checked how many languages and accents each handles, how well, and whether it works across both audio and video input.
- Adaptive learning: These tools are programmed with self-improving techniques like machine learning or NLP. I checked how these tools sharpen accuracy on your vocabulary as they take in more audio and corrections over time, be it customer service, assistive jobs, logistics, or inventory handling.
- Hands-free operations and accessibility: I gave weight to genuinely hands-free use for people who can’t rely on a keyboard, including those with carpal tunnel or Tourette’s: can someone drive the tool by voice alone, through noise, without slowing down?
- AI features beyond transcription: Today the differentiator is what sits on top of the transcript: summarization, sentiment, speaker diarization, redaction, and LLM-driven audio analysis. I analyzed how G2 scores these tools under Advanced AI and Agentic AI and where a tool pulls ahead of plain speech-to-text.
- Pricing and cost model. Pricing splits sharply here: usage-based per-minute or per-hour APIs versus per-seat subscriptions, with free tiers that vary widely. I’d weigh the model against your volume, since the lowest sticker rate isn’t always cheapest at scale.
Over the several weeks, I researched 20+ voice recognition tools. I narrowed down the best 9 based on conversational intelligence, audio and video integration, and robust transcription abilities, and I am presenting them in this listicle for you and your teams to consider.
The list below contains genuine user reviews from the voice recognition category page. To be included in this category, a solution must:
- Convert spoken words into written text
- Identify speech patterns to recognize words
- Understand and process speech in at least one language
- Capture and analyze sound from a microphone or audio file
- Provide some level of correction for misrecognized words
*This data was pulled from G2 in 2026. Some reviews may have been edited for clarity.
1. Deepgram: Best for developers needing fast, accurate transcription APIs
Deepgram is a developer-first speech-to-text platform that turns recorded audio and live streams into fast, accurate transcripts through a single API, then lets you format, search, or pipe that text into other tools. It’s the use case I kept seeing it built for as I worked through its reviews.
It earns the highest satisfaction score (93 on 100) in the category. Across more than 400 G2 reviews, it holds a 4.6 out of 5 rating, with 98% of users rating it 4 or 5 stars and 91% saying they’d recommend it. G2 Data rates its developer API and SDK at 95%, the strongest of this functionality in this roundup.
I’d start with accuracy, because it’s the theme reviewers raise most. In the recent G2 reviews I analyzed, the common note is clean output on clear English audio, including technical jargon and domain terms that trip up other engines, which means less time correcting transcripts before they’re usable.
The API is the part developers single out first. Reviewers describe it as clean and quick to wire up, the kind of interface you call from your own app without fighting it, which lowers the cost of building speech-to-text into a product.
What stood out as I compared the field is real-time performance. Low latency is Deepgram’s single most distinctive theme in the reviews; reviewers describe near-instant streaming transcription with no noticeable lag, which is what live captioning and voice agents actually need.
Getting started is unusually quick. Reviewers repeatedly call the initial setup easy, and G2 Data agrees: installation and setup is one of its top-rated capabilities, and it’s one of the quickest tools here to get live. Teams can prove it out before committing real engineering time.
The model options let teams tune for their use case. Reviewers point to streaming and prebuilt models they can fine-tune for customer-service calls, technical audio, or niche vocabularies, so one platform covers very different workloads.
I noticed reviewers who’ve run other engines tend to rate Deepgram the better deal. A recurring recent note compares it favorably with others on this list, like Azure, Google Cloud, and Whisper, on speed, word-error rate, and price, the trade-off a developer weighs most.
English is where Deepgram is strongest, and that cuts both ways. It handles English, including accented English, very well, but a meaningful number of reviewers note regional and Indic languages and broader multilingual detection still lag, and G2 Data scores multilingual recognition as its weakest feature. If your work is English-first this rarely surfaces; if you transcribe across many languages, some teams pair it with a second engine, so test it on your own language mix first.
I’d also highlight speaker handling for multi-party recordings, since single-speaker audio is rarely affected. Across recent G2 reviews, some users find diarization mixes up voices when people talk over each other and can’t always name speakers or add timestamps without extra work, and G2 Data puts speaker differentiation below category average. For clean single streams it won’t slow you down but for meeting and group-call transcription it’s worth a check.
For teams building English-language voice features who care most about speed and accuracy, Deepgram is the one I’d shortlist first. It pairs a clean developer API with real-time performance reviewers rate at the top of this category.
What I like about Deepgram:
- When I read through the G2 reviews, accuracy on clean English audio is the praise that comes up most. Reviewers especially value that it handles technical and domain-specific terms well, which makes the transcripts more useful for calls, interviews, meetings, and media workflows.
- Reviewers also keep pointing to the speed, with some describing long audio files transcribed in roughly a minute. For teams processing calls, podcasts, or meeting recordings at volume, that fast turnaround makes transcription feel like part of the workflow rather than a bottleneck.
What G2 users like about Deepgram:
“The fast transcription rates significantly improve time management by transcribing hours of audio in seconds, streamlining my workflow and enabling more interviews. Moreover, Deepgram’s API is straightforward to integrate, creating an effortless experience for developing independent tools. The quality of transcriptions is greatly enhanced, and the ability to catalog based on efficiency, success rate, and accuracy is invaluable. Overall, Deepgram is not only reliable and cost-effective but is also a de facto choice for speech-to-text models. It’s clearly a 10 for me, and I’ve already recommended it to colleagues because of the ongoing improvements and planned developments.”
– Deepgram review, Muhammad A.
What I dislike about Deepgram:
- Deepgram is strongest for English-first transcription, so multilingual teams should test their specific languages before rollout. Reviewers praise its English accuracy, while some say regional and Indic-language coverage can be less consistent.
- Speaker separation can struggle when voices overlap or recordings get messy. For clean audio, single-speaker files, or interviews with clear turns, Deepgram’s transcription quality is still the bigger draw
What G2 users dislike about Deepgram:
“Sometimes the multi-language support doesn’t work perfectly. When calling customers who speak Indonesian or Dubai dialects, it doesn’t detect their language well.”
– Deepgram review, Aman S.
2. Google Cloud Speech-to-Text: Best for teams on Google Cloud scaling multilingual, real-time transcription
Google Cloud Speech-to-Text is Google’s cloud transcription API that turns audio and live streams into text across 125+ languages, using Google’s own speech models (now the Chirp family) and tight integration with the rest of Google Cloud. It’s the option I kept seeing global, cloud-based teams reach for.
It carries the largest market presence in the category and across more than 200 G2 reviews it holds a 4.6 out of 5 rating, with 97% of users rating it 4 or 5 stars. In G2 Data, software integration (100%) and multilingual recognition (98%) sit at the top of its card.
What I’d put first is the language coverage. G2 reviewers point to support for well over 100 languages and dialects, the reason it’s a default for global teams transcribing client calls or building multilingual products. G2 Data rates multilingual recognition among its strongest features.
It handles context, not just words. Reviewers describe it correcting mispronunciations, adding punctuation, and reading meaning from the surrounding sentence, so transcripts need less cleanup before they’re usable.
Integration is where I saw it score highest. Several reviewers say it slots cleanly into other Google Cloud services and third-party tools, and G2 Data puts software integration at the top of its features, which matters when transcription is one step in a pipeline feeding chatbots or search.
I saw real-time streaming transcription come up often, with reviewers relying on it for live, multi-accent audio where they need text as people speak.
Speaker diarization separates voices in group calls and meetings, and G2 Data scores speaker differentiation among its highest features, so multi-party transcripts come back labeled rather than as one block.
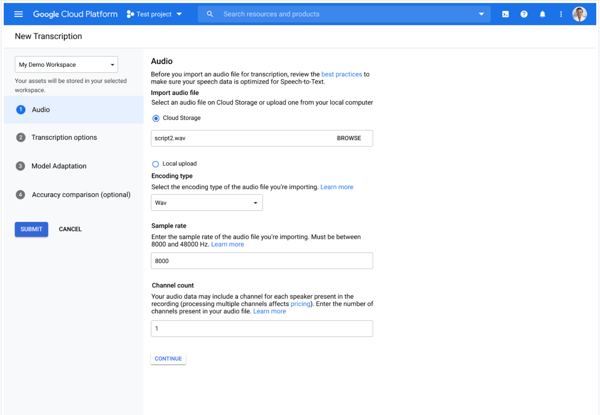
It ingests varied inputs, calls, video meetings, and recordings, and converts them reliably, which G2 reviewers credit for fitting different workflows without extra tooling.
I’d plan usage before moving past the free credits. It can feel inexpensive during testing, but reviewers say costs climb once transcription becomes a recurring, high-volume workflow. The upside is that the pricing scales with usage, so teams with predictable audio volume can model spend before rollout instead of staffing or maintaining transcription infrastructure themselves.
Accuracy is strongest on clear audio, but the area I’d test carefully is messy input. Reviewers note that heavier regional accents, including some noisy recordings or can require more correction, and G2 Data scores accuracy in noisy settings as its weakest feature (at 83% against category average of 88%). For clean recordings, meetings, interviews, and controlled audio, that issue is much less likely to show up. For call-center audio or mixed-accent environments, I’d run a sample set first so the team knows how much review time to expect.
Many global teams already on Google Cloud see it as a dependable, enterprise-ready solution. For projects that need broad language coverage and clean integration, Speech-to-Text is one of the most capable options here.
What I like about Google Cloud Speech-to-Text:
- When I read the reviews, language coverage is the standout for most. G2 reviewers describe transcribing client calls in their native languages across well over 100 of them.
- Reviewers also keep crediting how cleanly it integrates with the rest of Google Cloud and third-party tools, which I saw tied repeatedly to building it into bigger workflows.
What G2 users like about Google Cloud Speech-to-Text:
“I find it very much useful in my workplace meetings where I need to frequently interact with foreign clients and when they are now able to convey the requirements to me easily in their native language, and that was transcribed in to english in email and vice versa for the client.” – Google Cloud Speech-to-Text review, Akash A.
What I dislike about Google Cloud Speech-to-Text:
- I’d watch the bill on heavy use: reviewers say it’s fine within the free credits, but costs add up faster than expected once you’re past them. For teams with predictable audio workloads, Google Cloud Speech-to-Text is easier to scale without managing transcription infrastructure yourself.
- Accuracy is most worth testing on messy audio. Reviewers note heavier accents and noisy recordings may need more correction, but for clear recordings, meetings, and controlled audio workflows, Google Cloud Speech-to-Text remains much easier to rely on.
What G2 users dislike about Google Cloud Speech-to-Text:
“I have noticed that transcription accuracy can sometimes become slightly lower in noisy environment or when background sound is not very clear, especially in longer educational recordings or webinar style audio. In some cases I need to make small manual corrections if speaker speed changes frequently or multiple audio variations are present together.”
– Google Cloud Speech-to-Text review, Ishan S.
Learn the basics of voice recognition and its applications to develop a robust and accessible voice engine or assistant.
3. Krisp: Best for remote teams removing background noise from live calls
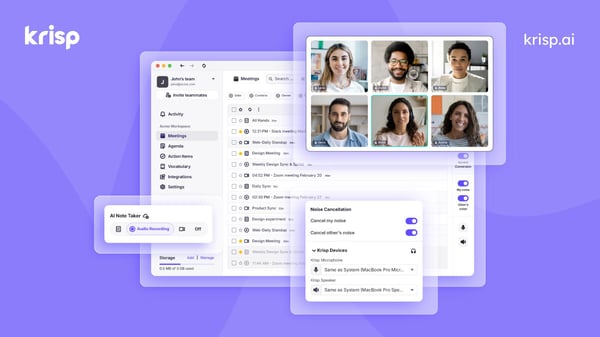
Krisp is an AI voice-clarity app that sits on top of whatever calling or meeting tool you already use, cancels background noise in real time, and transcribes and summarizes the conversation. It’s the tool I’d hand to anyone who lives on video calls from a less-than-quiet space.
It holds 4.7 out of 5 rating across more than 1,100 reviews, where 99% of users score it 4 or 5 stars and 95% say they’d recommend it. On G2 it shows up in three categories at once, noise cancellation, AI note-taking, and meeting assistants, which I saw people actually use it: to clean up their audio, capture the notes, and summarize the call.
I’d start with the noise cancellation, because it’s what makes Krisp distinct. It’s the only tool in this roundup built around stripping background sound from a live call, and reviewers describe it blocking everything from open-office chatter to, in one case, a screeching parrot, so you sound clear without needing a quiet room. G2 Data rates its accuracy in noisy settings above the category (at 92% against the category average of 88%).
It works on top of whatever app you already run, which is the first thing I look for in a tool like this. Reviewers on Zoom, Teams, Google Meet, and dialers say Krisp transcribes calls regardless of platform, so a team doesn’t have to standardize on one tool to get clean audio and a transcript.
Meeting transcription with searchable notes is the most-praised capability in the reviews I analyzed. Users describe getting a full, searchable record of each call they can revisit later, the difference between remembering a decision and reconstructing it.
What I saw reviewers lean on next is the AI summaries and action items. Beyond the raw transcript, Krisp pulls out a summary and the to-dos, so a back-to-back caller can act on what was agreed without rewatching.
Accent and voice clarity is a quieter strength I’d name. Reviewers who work across borders mention Krisp adjusting tone and pronunciation so they come through more clearly on international calls, which matters for distributed and offshore teams.
I also noticed Krisp can capture a call without sending a bot into the meeting. Reviewers value that it records and transcribes in the background rather than joining as a visible participant, which feels less invasive to clients and still leaves a searchable recording.
Reviewers say Krisp’s desktop app is still the fuller experience, while the mobile app doesn’t yet support phone-call transcription in the way some users want. If most of your calls happen from a laptop, this rarely gets in the way. If your team captures calls on the go, I’d check the mobile feature set first; for desktop-first meetings and calls, Krisp’s core noise cancellation and transcription workflow remains the stronger fit.
Krisp installs in minutes and runs cleanly for most setups, so the narrower thing I’d still watch is audio-device detection. A few reviewers mention needing to reselect a microphone, restart the app, or troubleshoot when using non-USB headsets or juggling multiple audio devices. I’d treat that as a small hardware-routing check rather than a setup blocker: once the right mic is selected, Krisp generally stays easy to run in the background.
For remote and client-facing teams who spend their days on calls from imperfect spaces, Krisp is the one I’d reach for first. It does the unglamorous work, clean audio, a reliable transcript, and a usable summary, with so little setup.
What I like about Krisp:
- When I read the reviews, the noise cancellation is the feature people credit most, with users describing it erasing everything from office chatter to household noise so they sound professional on any call.
- Reviewers also keep pointing to the transcription and summaries. I saw many describe getting searchable notes and action items from calls across whatever platform they use.
What G2 users like about Krisp:
“I use Krisp for meetings in Teams and what I most like about it is the main function which blocks all sounds around me and keeps my voice clear. Since I work from home, it is really important that no sounds other than my voice come through, and Krisp does its job well. I am happy with the service and enjoy using it. The initial setup was real easy, which is great because it adds to its convenience. I recommended Krisp to a couple of people who also work from home because it’s important to cut all sounds, and Krisp does it effectively.”
– Krisp review, Ivan M.
What I dislike about Krisp:
- I’d check the mobile app if your team captures calls away from a laptop. Reviewers say desktop is still the fuller experience, but for laptop-first meetings, Krisp’s core workflow remains strong.
- Setup is quick, though a few mention small microphone-detection issues on non-USB or multi-device setups. Once the right mic is selected, Krisp is easy to leave running in the background.
What G2 users dislike about Krisp:
“Sometimes it doesn’t adapt my mic when I’m not using a USB device. I can say the setup is medium because you really have to be a little tech or I need to assist them to set it up. It would be helpful if Krisp could create a short video on how to set up or connect the correct device to make sure the noise canceling is correct.”
– Krisp review, Jennith Freny B.
4. AssemblyAI – Speech to Text API: Best for product teams adding AI audio intelligence like summarization and sentiment
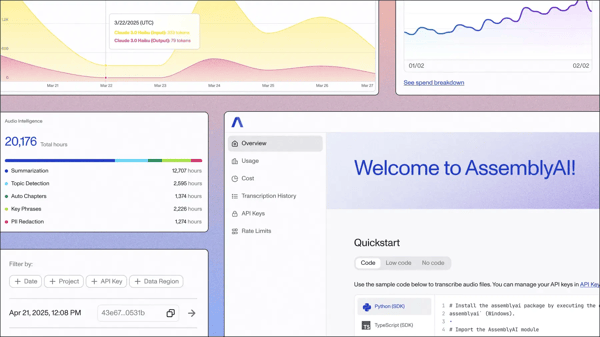
AssemblyAI – Speech to Text API is a speech-to-text API built for developers, with a layer of AI models, summarization, speaker labels, topic and entity detection, sitting on top of the transcript. It’s the option I’d point product teams to when they want understanding, not just text.
It’s rated 4.6 out of 5 across more than 100 reviews, where 98% score it 4 or 5 stars. Its reviewer base skews technical, with Computer Software and IT among the leading industries, and G2 Data shows one of the faster reported paybacks in the category at 6 months.
What I’d point to first is the transcripts, since nothing downstream survives if those are wrong. Reviewers say they hold up where audio gets hard, technical jargon, several voices on one call, the occasional heavy accent, and in the reviews I read, that reliability is the part they stop worrying about.’
What made the developer experience stand out to me was how quickly reviewers said they could get moving. AssemblyAI is built for API-first teams, and reviewers describe getting from signup to a working call without much friction. G2 Data also rates its developer API among the stronger features, which fits the use case: this is for teams that want to integrate transcription into a product, not manually upload files one by one.
The bigger reason I’d choose AssemblyAI over a plain transcription endpoint is the prebuilt model layer. Speaker labels, summaries, topics, entities, and redaction come through one API, which saves teams from building and maintaining that logic themselves. For call analysis, meeting intelligence, media search, support workflows, or research tools, that prebuilt structure is what makes the output immediately more useful.
Documentation rarely earns a mention, so it stands out that reviewers raise it on their own. Reviewers bring up the docs as clear and easy to follow, which is worth calling out because bad API documentation can slow even a strong product. Here, the documentation seems to reduce the usual integration drag and helps explain why first tests move quickly.
Source: AssemblyAI
I also noticed the privacy-adjacent features make it useful in more sensitive workflows. Anonymous speaker labels and redaction help teams keep transcripts usable without exposing every name, entity, or speaker detail in the final output. That is especially relevant for teams working with healthcare, therapy, finance, or other audio where the transcript needs to be useful but handled carefully.
The product momentum is another real advantage. Reviewers describe AssemblyAI as a vendor that ships often, with newer models like Universal and Slam-1 coming up in G2 user feedback. That makes it feel like a safer API bet for product teams because improvements to accuracy and understanding can keep arriving without the team rebuilding the audio stack themselves.
I’d model cost before moving it into a high-volume product. Reviewers like that AssemblyAI is cheap and easy to start with, especially with the free tier and trial credits, but several say spend climbs once usage grows or advanced models stack up. For prototypes and controlled workloads, that low-friction start is a strength; for production teams, pricing it early keeps the bill tied to the value the API is creating.
Speed is the tradeoff I’d test at the edges. A few G2 reviewers say ordinary recorded clips are fine, but hour-long files, very large jobs, and live conversation can feel slower or more batch-oriented than some teams expect. For standard async audio workflows, that should not get in the way; AssemblyAI is strongest when you want accurate recorded-audio transcripts with intelligence layered on top.
Hand a developer AssemblyAI when they want the transcript to arrive sorted, speakers identified, topics tagged, a summary ready to use.
What I like about AssemblyAI – Speech to Text API:
- The reviews I read keep landing on the same pairing: accurate transcripts and a developer-friendly API. Reviewers praise the transcription quality on clean English audio, including technical and domain-specific terms, while also describing the setup as quick enough to move from signup to a working call without much friction.
- The prebuilt AI models are the other major reason to use it. Speaker labels, summaries, topics, entities, and redaction give teams structured output they would otherwise have to build and maintain themselves, which is what makes AssemblyAI stronger than a plain transcription endpoint.
What G2 users like about AssemblyAI – Speech to Text API:
“AssemblyAI’s Speech-to-Text API was quick for our team to integrate, and it delivers accurate transcription results even with long audio files and conversations involving multiple speakers. The documentation is easy to understand, and the setup process was smooth end to end. Features such as speaker identification, summarization, and real-time transcription saved us a lot of development time because we didn’t have to build those capabilities ourselves. In regular use, the API feels fast, reliable, and straightforward to work with. It also scales well, which makes it a good fit for both small projects and larger production applications.”
–