


LangChain is likely one of the hottest improvement platforms for creating purposes that use generative AI—but it surely’s solely accessible for Python and JavaScript. What to do for those who’re an R programmer who desires to make use of LangChain?
Happily, you are able to do a number of helpful issues in LangChain with fairly fundamental Python code. And, because of the reticulate R bundle, R and RStudio customers can write and run Python within the setting they’re comfy with—together with passing objects and knowledge forwards and backwards between Python and R.
On this LangChain tutorial, I will present you tips on how to work with Python and R to entry LangChain and OpenAI APIs. This may allow you to use a giant language mannequin (LLM)—the expertise behind ChatGPT—to question ggplot2‘s 300-page PDF documentation. Our first pattern question: “How do you rotate textual content on the x-axis of a graph?”
This is how the method breaks down, step-by-step:
- If you have not already, arrange your system to run Python and
reticulate. - Import the
ggplot2PDF documentation file as a LangChain object with plain textual content. - Break up the textual content into smaller items that may be learn by a big language mannequin, since these fashions have limits to how a lot they’ll learn without delay. The 300 pages of textual content will exceed OpenAI’s limits.
- Use an LLM to create “embeddings” for every chunk of textual content and save all of them in a database. An embedding is a string of numbers that represents the semantic which means of textual content in multidimensional house.
- Create an embedding for the consumer’s query, then examine the query embedding to all the prevailing ones from the textual content. Discover and retrieve essentially the most related textual content items.
- Feed solely these related parts of textual content to an LLM like GPT-3.5 and ask it to generate a solution.
If you are going to comply with the examples and use the OpenAI APIs, you will want an API key. You’ll be able to join at platform.openai.com. If you happen to’d relatively use one other mannequin, LangChain has elements to construct chains for quite a few LLMs, not solely OpenAI’s, so you are not locked in to 1 LLM supplier.
LangChain has the elements to deal with most of those steps simply, particularly for those who’re happy with its defaults. That is why it is turning into so standard.
Let’s get began.
Step 1: Arrange your system to run Python in RStudio
If you happen to already run Python and reticulate, you possibly can skip to the subsequent step. In any other case, let’s be sure to have a current model of Python in your system. There are lots of methods to put in Python, however merely downloading from python.org labored for me. Then, set up the reticulate R bundle the same old approach with set up.packages("reticulate").
If you happen to’ve bought Python intalled however reticulate cannot discover it, you should use the command use_python("/path/to/your/python").
It is good Python apply to make use of digital environments, which let you set up bundle variations that will not battle with the necessities of different initiatives elsewhere in your system. This is tips on how to create a brand new Python digital setting and use R code to put in the packages you will want:
library(reticulate)
virtualenv_create(envname = "langchain_env", packages = c( "langchain", "openai", "pypdf", "bs4", "python-dotenv", "chromadb", "tiktoken")) # Solely do that as soon as
Be aware that you could title your setting no matter you want. If you might want to set up packages after creating the setting, use py_install(), like this:
py_install(packages = c( "langchain", "openai", "pypdf", "bs4", "python-dotenv", "chromadb", "tiktoken"), envname = "langchain_env")
As in R, you must solely want to put in packages as soon as, not each time you might want to use the setting. Additionally, do not forget to activate your digital setting, with
use_virtualenv("langchain_env")
You will do that every time you come again to the venture and earlier than you begin operating Python code.
You’ll be able to take a look at whether or not your Python setting is working with the compulsory
reticulate::py_run_string('
print("Good day, world!")
')
You’ll be able to set your OpenAI API key with a Python variable for those who like. Since I have already got it in an R setting variable, I normally set the OpenAI API key utilizing R. It can save you any R variable to a Python-friendly format with reticulate’s r_to_py() operate, together with setting variables:
api_key_for_py <- r_to_py(Sys.getenv("OPENAI_API_KEY"))
That takes the OPENAI_API_KEY setting variable, ensures it is Python-friendly, and shops it in a brand new variable: api_key_for_py (once more, the title will be something).
Finally, we’re able to code!
Step 2: Obtain and import the PDF file
I’ll create a brand new docs subdirectory of my foremost venture listing and use R to obtain the file there.
# Create the listing if it does not exist
if(!(dir.exists("docs"))) {
  dir.create("docs")
}

# Obtain the file
obtain.file("https://cran.r-project.org/net/packages/ggplot2/ggplot2.pdf", destfile = "docs/ggplot2.pdf", mode = "wb")
Subsequent comes the Python code to import the file as a LangChain doc object that features content material and metadata. I will create a brand new Python script file referred to as prep_docs.py for this work. I might hold operating Python code proper inside an R script by utilizing the py_run_string() operate as I did above. Nonetheless, that is not superb for those who’re engaged on a bigger activity, since you lose out on issues like code completion.
Vital level for Python newbies: Do not use the identical title in your script file as a Python module you will be loading! In different phrases, whereas the file does not must be referred to as prep_docs.py, do not title it, say, langchain.py if you can be importing the langchain bundle! They’re going to battle. This is not a problem in R.
This is the primary a part of my new prep_docs.py file:
# If operating from RStudio, bear in mind to first run in R:
# library(reticulate)
# use_virtualenv("the_virtual_environment_you_set_up")
# api_key_py <- r_to_py(Sys.getenv("OPENAI_API_KEY"))

from langchain.document_loaders import PyPDFLoader
my_loader = PyPDFLoader('docs/ggplot2.pdf')
# print(kind (my_loader))
all_pages = my_loader.load()
# print(kind(all_pages))
print( len(all_pages) )
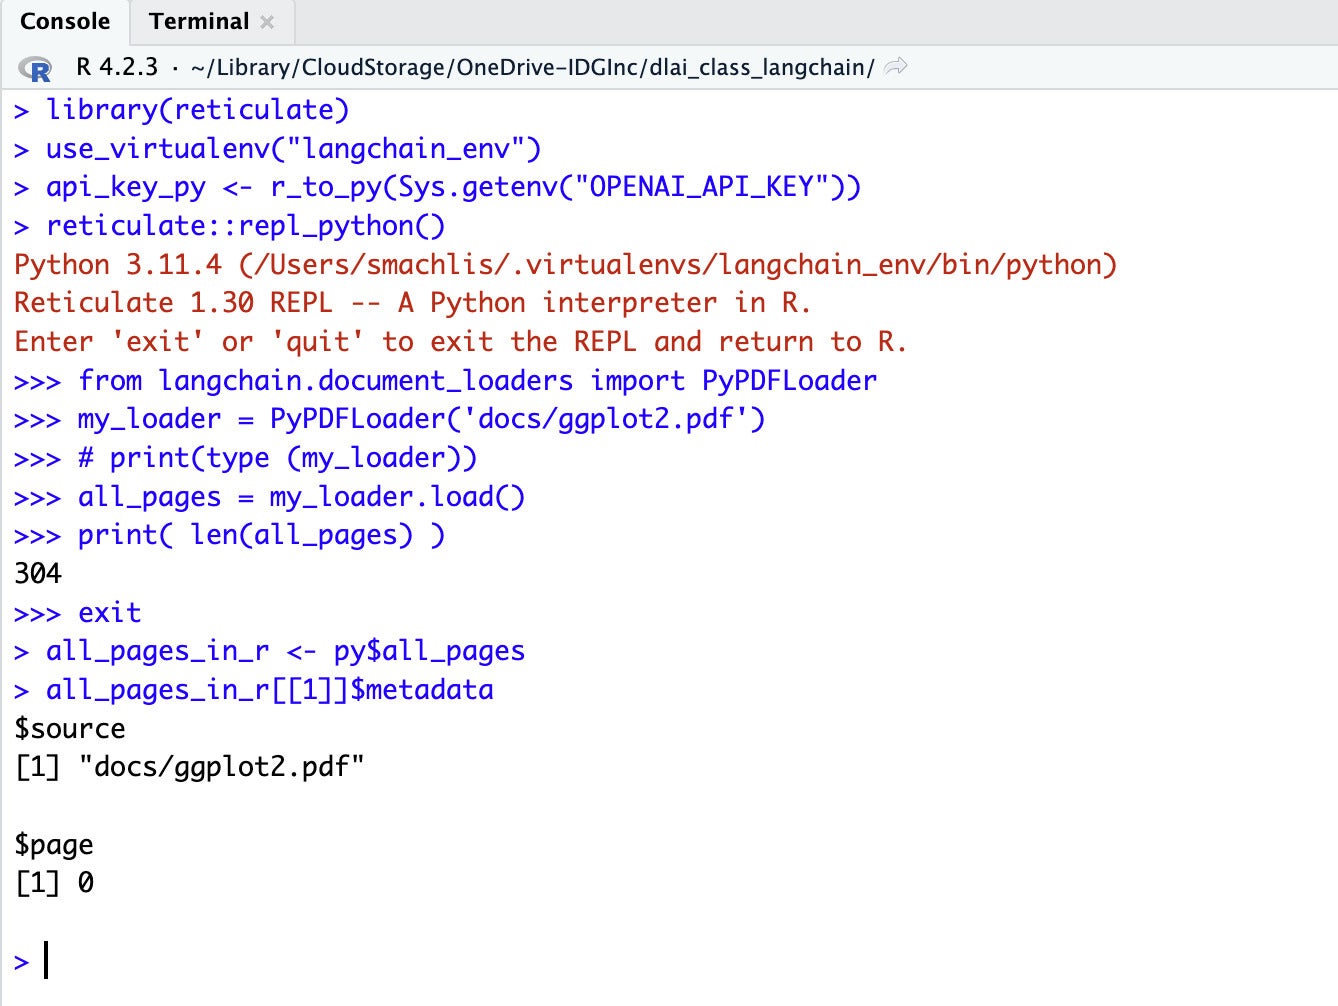
This code first imports the PDF doc loader PyPDFLoader. Subsequent, it creates an occasion of that PDF loader class. Then, it runs the loader and its load methodology, storing the ends in a variable named all_pages. That object is a Python listing.
I’ve included some commented strains that may print the item varieties if you would like to see them. The ultimate line prints the size of the listing, which on this case is 304, one for every web page within the PDF.
You’ll be able to click on the supply button in RStudio to run a full Python script. Or, spotlight some strains of code and solely run these, simply as with an R script. The Python code appears to be like a bit of completely different when operating than R code does, because it opens a Python interactive REPL session proper inside your R console. You will be instructed to kind exit or stop (with out parentheses) to exit and return to your common R console while you’re completed.
 Sharon Machlis for IDG
You’ll be able to study the all_pages Python object in R by utilizing reticulate‘s py object. The next R code shops that Python all_pages object into an R variable named all_pages_in_r (you possibly can name it something you would like). You’ll be able to then work with the item like another R object. On this case, it is a listing.
all_pages_in_r <- py$all_pages
# Examples:
all_pages_in_r[[1]]$metadata # See metadata within the first merchandise
nchar(all_pages_in_r[[100]]$page_content) # Rely variety of characters within the one centesimal merchandise
Step 3: Break up the doc into items
LangChain has a number of transformers for breaking apart paperwork into chunks, together with splitting by characters, tokens, and markdown headers for markdown paperwork. One beneficial default is the RecursiveCharacterTextSplitter, which “recursively tries to separate by completely different characters to search out one which works.” One other standard possibility is the CharacterTextSplitter, which is designed to have the consumer set its parameters.
You’ll be able to set this splitter’s most text-chunk measurement, whether or not it ought to rely by characters or LLM tokens (tokens are sometimes one to 4 characters), and the way a lot the chunks ought to overlap. I hadn’t considered the necessity to have textual content chunks overlap till I started utilizing LangChain, but it surely is smart except you possibly can separate by logical items like chapters or sections separated by headers. In any other case, your textual content could get break up mid-sentence, and an essential piece of data might find yourself divided between two chunks, with out the total which means being clear in both.
You may also choose what separators you need the splitter to prioritize when it divvies up your textual content. CharacterTextSplitter‘s default is to separate first on two new strains (nn), then one new line, an area, and at last no separator in any respect.
The code under imports my OpenAI API key from the R api_key_for_py variable by utilizing reticulate’s r object within Python. It additionally hundreds the openai Python bundle and LangChain’s Recursive Character Splitter, creates an occasion of the RecursiveCharacterTextSplitter class, and runs that occasion’s split_documents() strategies on the all_pages chunks.
import openai
openai.api_key = r.api_key_for_py
from langchain.text_splitter import RecursiveCharacterTextSplitter
my_doc_splitter_recursive = RecursiveCharacterTextSplitter()
my_split_docs = my_doc_splitter_recursive.split_documents(all_pages)
Once more, you possibly can ship these consequence to R with R code akin to:
my_split_docs <- py$my_split_docs
Are you questioning what’s the most variety of characters in a bit? I can verify this in R with a bit of customized operate for the listing:
get_characters <- operate(the_chunk) {
x <- nchar(the_chunk$page_content)
return(x)
}

purrr::map_int(my_split_docs, get_characters) |>
max()
That generated 3,985, so it appears to be like just like the default chunk most is 4,000 characters.
If I needed smaller textual content chunks, I would first attempt the CharacterTextSplitter and manually set chunk_size to lower than 4,000, akin to
chunk_size = 1000
chunk_overlap = 150
from langchain.text_splitter import CharacterTextSplitter
c_splitter = CharacterTextSplitter(chunk_size=chunk_size, chunk_overlap=chunk_overlap, separator=" ")
c_split_docs = c_splitter.split_documents(all_pages)
print(len(c_split_docs)) # To see in Python what number of chunks there at the moment are
I can examine the ends in R in addition to Python:
c_split_docs <- py$c_split_docs
size(c_split_docs)
That code generated 695 chunks with a most measurement of 1,000.
What’s the associated fee?
Earlier than going additional, I would prefer to know if it is going to be insanely costly to generate embeddings for all these chunks. I will begin with the default recursive splitting’s 306 objects. I can calculate the full variety of characters in these chunks on the R object with:
purrr::map_int(my_split_docs, get_characters) |>
  sum()
The reply is 513,506. Conservatively estimating two characters per token, that might work out to round 200,000.
If you wish to be extra precise, the TheOpenAIR R bundle has a count_tokens() operate (be certain that to put in each that and purrr to make use of the R code under):
purrr::map_int(my_split_docs, ~ TheOpenAIR::count_tokens(.x$page_content)) |>
   sum()
That code exhibits 126,343 tokens.
How a lot would that price? OpenAI’s mannequin designed to generate embeddings is ada-2. As of this writing ada-2 prices $0.0001 for 1K tokens, or about 1.3 cents for 126,000. That is inside funds!
Step 4: Generate embeddings
LangChain has pre-made elements to each create embeddings from textual content chunks and retailer them. For storage, I will use one of many easiest choices accessible in LangChain: Chroma, an open-source embedding database that you should use regionally.
First, I will create a subdirectory of my docs listing with R code only for the database, because it’s recommended to not have something however your database in a Chroma listing. That is R code:
if(!dir.exists("docs/chroma_db")) {
  dir.create("docs/chromaba_db")
}
Under is a few Python code to generate the embeddings utilizing LangChain’s OpenAIEmbeddings. That presently defaults to OpenAI’s ada-2 mannequin, so that you needn’t specify it. LangChain helps plenty of different LLMs with its Embeddings class, although, together with Hugging Face Hub, Cohere, Llama-cpp, and Spacy.
The Python code under is barely modified from DeepLearning.AI’s LangChain Chat with Your Information on-line tutorial.
from langchain.embeddings.openai import OpenAIEmbeddings
embed_object = OpenAIEmbeddings()

from langchain.vectorstores import Chroma
chroma_store_directory = "docs/chroma_db"

vectordb = Chroma.from_documents(
    paperwork=my_split_docs,
    embedding=embed_object,
    persist_directory=chroma_store_directory
)

# Verify what number of embeddings had been created
print(vectordb._collection.rely())
Be aware the underscore in _collection.rely()!
I see 306 embeddings, the identical quantity as my ggplot2 textual content chunks.
One other word for Python newbies: Indentation issues in Python. Ensure non-indented strains don’t have any areas earlier than them and indented strains all use the identical variety of indent areas.
It seems on my system that this code saved the info to disk. Nonetheless, the tutorial says we should always run the next Python code to avoid wasting the embeddings for later use. I will do this, too, since I do not need to must re-generate embeddings except the doc modifications.
vectordb.persist()
We’re now carried out with prepping the paperwork for querying. I will create a brand new file, qanda.py, to make use of the vector embeddings we have created.
Step 5: Embed the consumer question and discover doc chunks
Now it is time to ask a query, generate embeddings for that query, and retrieve the paperwork which are most related to the query based mostly on the chunks’ embeddings.
LangChain offers us a number of methods to do all of this in a single line of code, because of the vectordb object’s built-in strategies. Its similarity_search() methodology does an easy calculation of vector similarities and returns essentially the most related textual content chunks.
There are a number of different methods to do that, although, together with max_marginal_relevance_search(). The concept behind that one is you do not essentially need three textual content chunks which are nearly the identical. Perhaps you’d find yourself with a richer response if there was a bit of range within the textual content to get further helpful info. So, max_marginal_relevance_search() retrieves just a few extra related texts than you really plan to move to the LLM for a solution (you determine what number of extra). It then selects the ultimate textual content items, incorporating some extent of range.
You specify what number of related textual content chunks you would like similarity_search() to return with its ok argument. For max_marginal_relevance(), you specify what number of chunks ought to initially be retrieved with fetch_k, and what number of remaining textual content items you need the LLM to look via for its reply with ok.
I do not need to run the doc prep file if the paperwork have not modified, so I will first load the required packages and setting variables (i.e., my OpenAI API key) within the new qanda.py file, as I did earlier than utilizing doc_prep.py. Then, I will load my chromadb vector database:
# If operating from RStudio, bear in mind to first run in R:
# library(reticulate)
# use_virtualenv("the_virtual_environment_you_set_up")
# api_key_py <- r_to_py(Sys.getenv("OPENAI_API_KEY"))

import openai
openai.api_key = r.api_key_for_py
from langchain.embeddings.openai import OpenAIEmbeddings
embed_object = OpenAIEmbeddings()

from langchain.vectorstores import Chroma
chroma_store_directory = "docs/chroma_db"
vectordb = Chroma(persist_directory=chroma_store_directory,
                  embedding_function=embed_object)
Subsequent, I will hard-code a query and retrieve the related paperwork. Be aware that I can retrieve the paperwork with a single line of code:
my_question = "How do you rotate textual content on the x-axis of a graph?"
# For simple similarity looking out
sim_docs = vectordb.similarity_search(my_question)

# For optimum marginal relevance search retrieving 5 attainable chunks and selecting 3 finalists:
mm_docs = vectordb.max_marginal_relevance_search(my_question, ok = 3, fetch_k = 5)
If you wish to view the retrieved doc items, you possibly can print them in Python with one thing like the next:
for doc in mm_docs:
    print(doc.page_content)

for doc in sim_docs:
    print(doc.page_content)
Be aware the indents as a part of the for loops.
You may also view their metadata with:
for doc in mm_docs:
    print(doc.metadata)

for docs in sim_docs:
    print(docs.metadata)
As with the opposite objects, you can even have a look at these in R:
mm_relevant <- py$mm_docs
sim_relevant <- py$sim_docs
I am undecided why fashions generally return 4 paperwork after I ask for 3, however that should not be an issue—except it is too many tokens for the LLM when it goes via the textual content to generate a response.
Step 6: Generate your reply
It is now time to ask an LLM like GPT-3.5 to generate a written response to the consumer’s query based mostly on the related paperwork. You are able to do that with LangChain’s RetrievalQA operate.
I recommend first making an attempt LangChain’s default template for this, which is simple and infrequently works nicely for prototyping or your personal use:
# Arrange the LLM you need to use, on this instance OpenAI's gpt-3.5-turbo
from langchain.chat_models import ChatOpenAI
the_llm = ChatOpenAI(model_name="gpt-3.5-turbo", temperature=0)

# Create a series utilizing the RetrievalQA element
from langchain.chains import RetrievalQA
qa_chain = RetrievalQA.from_chain_type(the_llm,retriever=vectordb.as_retriever())

# Run the chain on the query, and print the consequence
print(qa_chain.run(my_question))
The AI despatched again the next response:
To rotate textual content on the x-axis of a graph, you should use the `theme()` operate in ggplot2. Particularly, you should use the `axis.textual content.x` argument to change the looks of the x-axis textual content. Right here is an instance:

```R
library(ggplot2)

# Create a fundamental scatter plot
p <- ggplot(mtcars, aes(x = mpg, y = wt)) +
  geom_point()

# Rotate x-axis textual content by 45 levels
p + theme(axis.textual content.x = element_text(angle = 45, hjust = 1))
```

On this instance, the `angle` argument is about to 45, which rotates the x-axis textual content by 45 levels. The `hjust` argument is about to 1, which aligns the textual content to the suitable. You'll be able to regulate the angle and alignment values to attain the specified rotation and alignment of the x-axis textual content.
Appears right!
Now that the chain is about up, you possibly can run it on different questions with only one command utilizing an R script:
py_run_string('
print(qa_chain.run("How can I make a bar chart the place the bars are metal blue?"))
')
This is the response:
```R
library(ggplot2)

# Create a bar chart with metal blue bars
p <- ggplot(mtcars, aes(issue(cyl)))
p + geom_bar(fill = "steelblue")
```

On this instance, we use the `fill` aesthetic to specify the colour of the bars as "steelblue". You'll be able to regulate the colour to your desire by altering the colour title or utilizing a hexadecimal colour code.
This can be a higher reply than I generally obtain when asking ChatGPT 3.5 the identical query. (Typically the code it sends again does not really work.)
You may additionally need to verify that the solutions aren’t being pulled from the overall ChatGPT information base, however are actually coming from the doc you uploaded. To seek out out, you would ask one thing utterly unrelated to ggplot2 that would not be within the documentation:
py_run_string('
print(qa_chain.run("What's the capital of Australia?"))
')
It is best to get again:
I do not know.
“I do not know” could also be a bit of terse for those who’re creating an software for wider use. You’ll be able to try the LangChain documentation if you would like to customise the default template. Personalizing the response is smart if you’re creating an software for greater than your self or a small crew .
Template tweaks is one space the place LangChain could really feel overly advanced—it will probably take a number of strains of code to implement small modifications to a template. Nonetheless, that is a threat in utilizing any opinionated framework, and it is as much as every developer to determine if the venture’s total advantages are value such prices. Whereas it’s enormously standard, not everyone seems to be a fan of LangChain.
What else are you able to do with LangChain?
The best addition to the applying thus far could be to incorporate extra paperwork. LangChain has a DirectoryLoader to make this simple. If you happen to’re looking out throughout a number of paperwork, you would possibly need to know which docs had been used to generate the response. You’ll be able to add the return_source_documents=True argument to RetrievalQA, like this:
qa_chain = RetrievalQA.from_chain_type(the_llm,retriever=vectordb.as_retriever(), return_source_documents=True)
my_result = qa_chain({"question": my_question})
print(my_result['result'])
The code is initially solely helpful to run regionally for a single consumer, but it surely may very well be the logic foundation for an interactive net software utilizing a framework like Streamlit or Shiny for Python. Or, you mix Python and R, ship the LLM’s remaining reply again to R, and create an software utilizing the Shiny R net framework (though I’ve found that deploying a Shiny app with each Python and R is considerably sophisticated).
Be aware, too, that this software is not technically a “chatbot” because it will not bear in mind your earlier questions. So, you could not have a “dialog” akin to “How can I modify the dimensions of a graph’s headline textual content?” adopted by “What in regards to the legend?” You’d must spell out every new query utterly, akin to “How do you modify the dimensions of a legend’s headline?”
Nonetheless, you would add reminiscence to the applying to show it right into a chatbot with LangChain’s ConversationBufferMemory.
Additional assets
To study extra about LangChain, along with the LangChain documentation, there’s a LangChain Discord server that options an AI chatbot, kapa.ai, that may question the docs.
I’ve labored via about one-third of Udemy’s Develop LLM powered purposes with LangChain by Eden Marco, and thus far it’s been useful. Whereas that course says you ought to be “proficient in Python,” I believe figuring out different programming languages together with willingness to do loads of looking out/ChatGPT-ing ought to be sufficient.
For information on Streamlit and LangChain, there are a number of tutorials on the Streamlit website, together with LangChain tutorial #1: Construct an LLM-powered app in 18 strains of code.
Lastly, Posit’s Winston Chang is engaged on an experimental chatstream bundle for Shiny Python that may embrace a “streaming” interface so the LLM response seems steadily by character or phrase, the way in which ChatGPT’s does, as an alternative of as in these examples.
Copyright © 2023 IDG Communications, Inc.

