

I blocked two of our rating pages utilizing robots.txt. We misplaced a place right here or there and the entire featured snippets for the pages. I anticipated much more influence, however the world didn’t finish.
Warning
I don’t advocate doing this, and it’s solely attainable that your outcomes could also be completely different from ours.
I used to be attempting to see the influence on rankings and visitors that the removing of content material would have. My idea was that if we blocked the pages from being crawled, Google must depend on the hyperlink alerts alone to rank the content material.
Nonetheless, I don’t suppose what I noticed was truly the influence of eradicating the content material. Perhaps it’s, however I can’t say that with 100% certainty, because the influence feels too small. I’ll be operating one other check to substantiate this. My new plan is to delete the content material from the web page and see what occurs.
My working idea is that Google should be utilizing the content material it used to see on the web page to rank it. Google Search Advocate John Mueller has confirmed this habits within the previous.
Thus far, the check has been operating for almost 5 months. At this level, it doesn’t look like Google will cease rating the web page. I think, after some time, it’ll doubtless cease trusting that the content material that was on the web page remains to be there, however I haven’t seen proof of that taking place.
Maintain studying to see the check setup and influence. The primary takeaway is that by accident blocking pages (that Google already ranks) from being crawled utilizing robots.txt in all probability isn’t going to have a lot influence in your rankings, and they’ll doubtless nonetheless present within the search outcomes.
I selected the identical pages as used within the “influence of hyperlink” examine, apart from the article on website positioning pricing as a result of Joshua Hardwick had simply up to date it. I had seen the influence of eradicating the hyperlinks to those articles and needed to check the influence of eradicating the content material. As I mentioned within the intro, I’m unsure that’s truly what occurred.
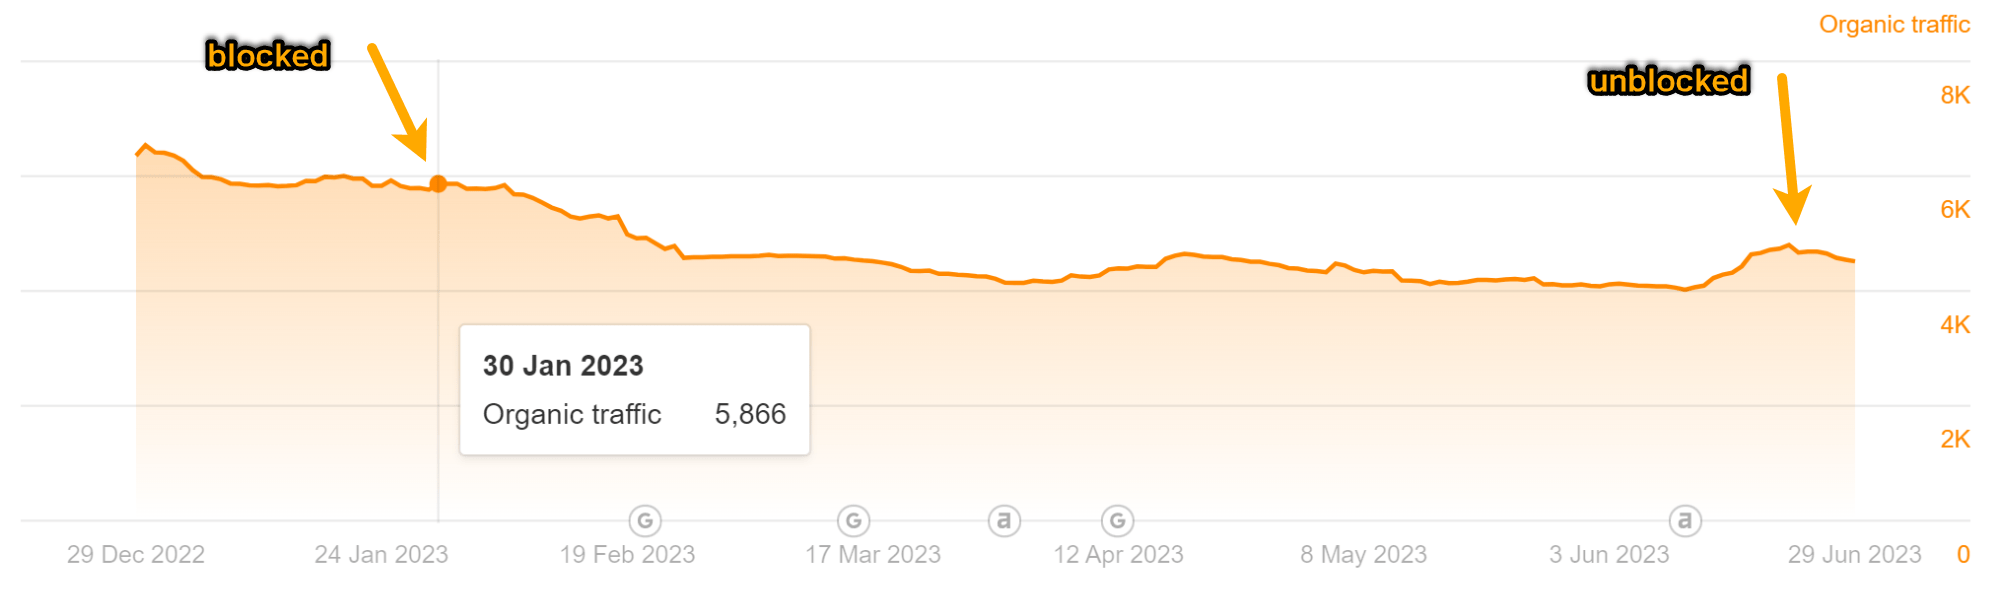
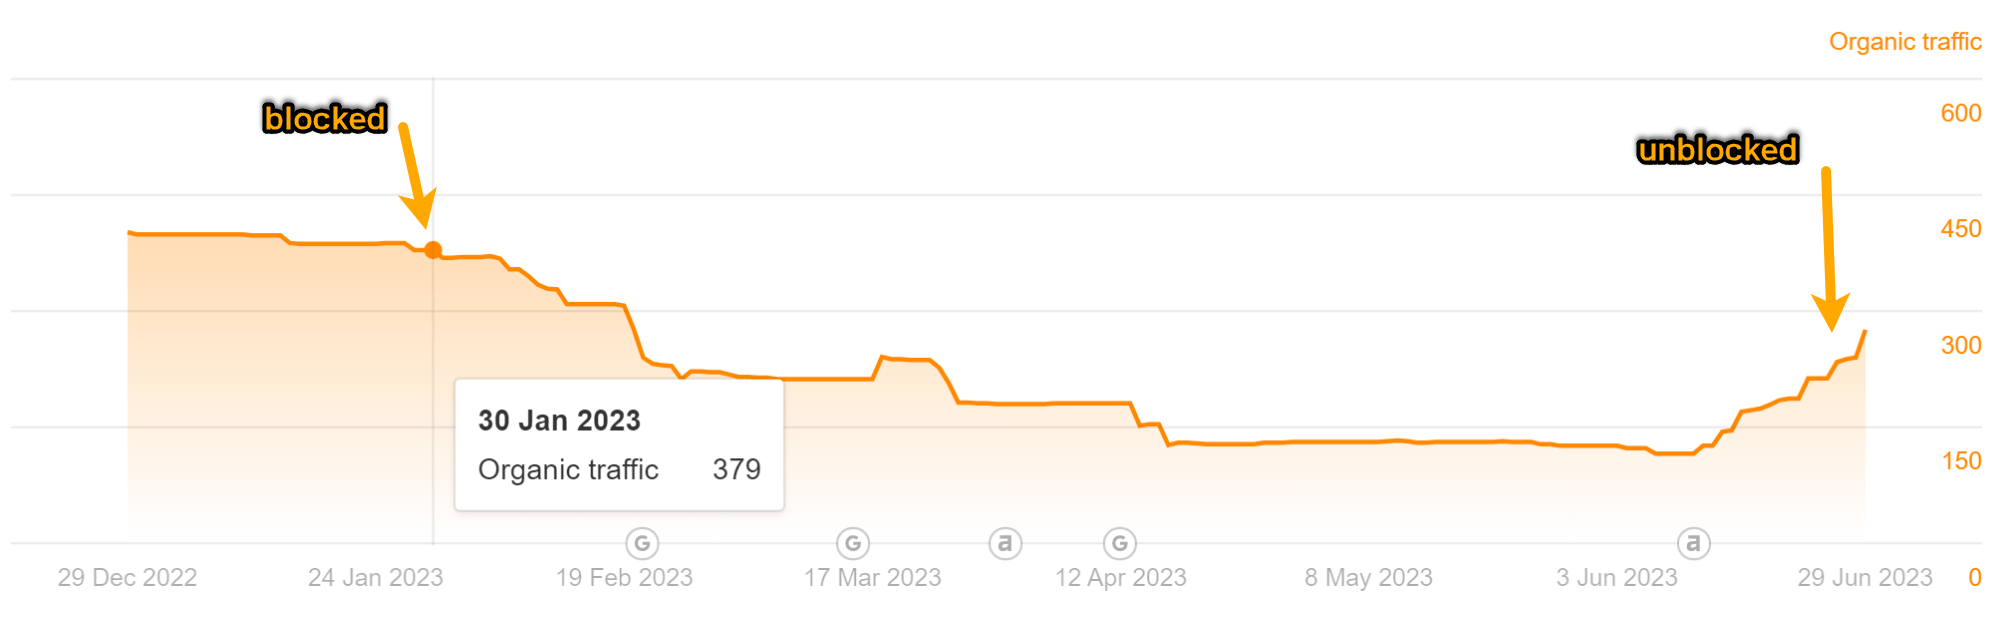
I blocked these two pages on January 30, 2023:
These strains had been added to our robots.txt file:
Disallow: /weblog/top-bing-searches/Disallow: /weblog/top-youtube-searches/
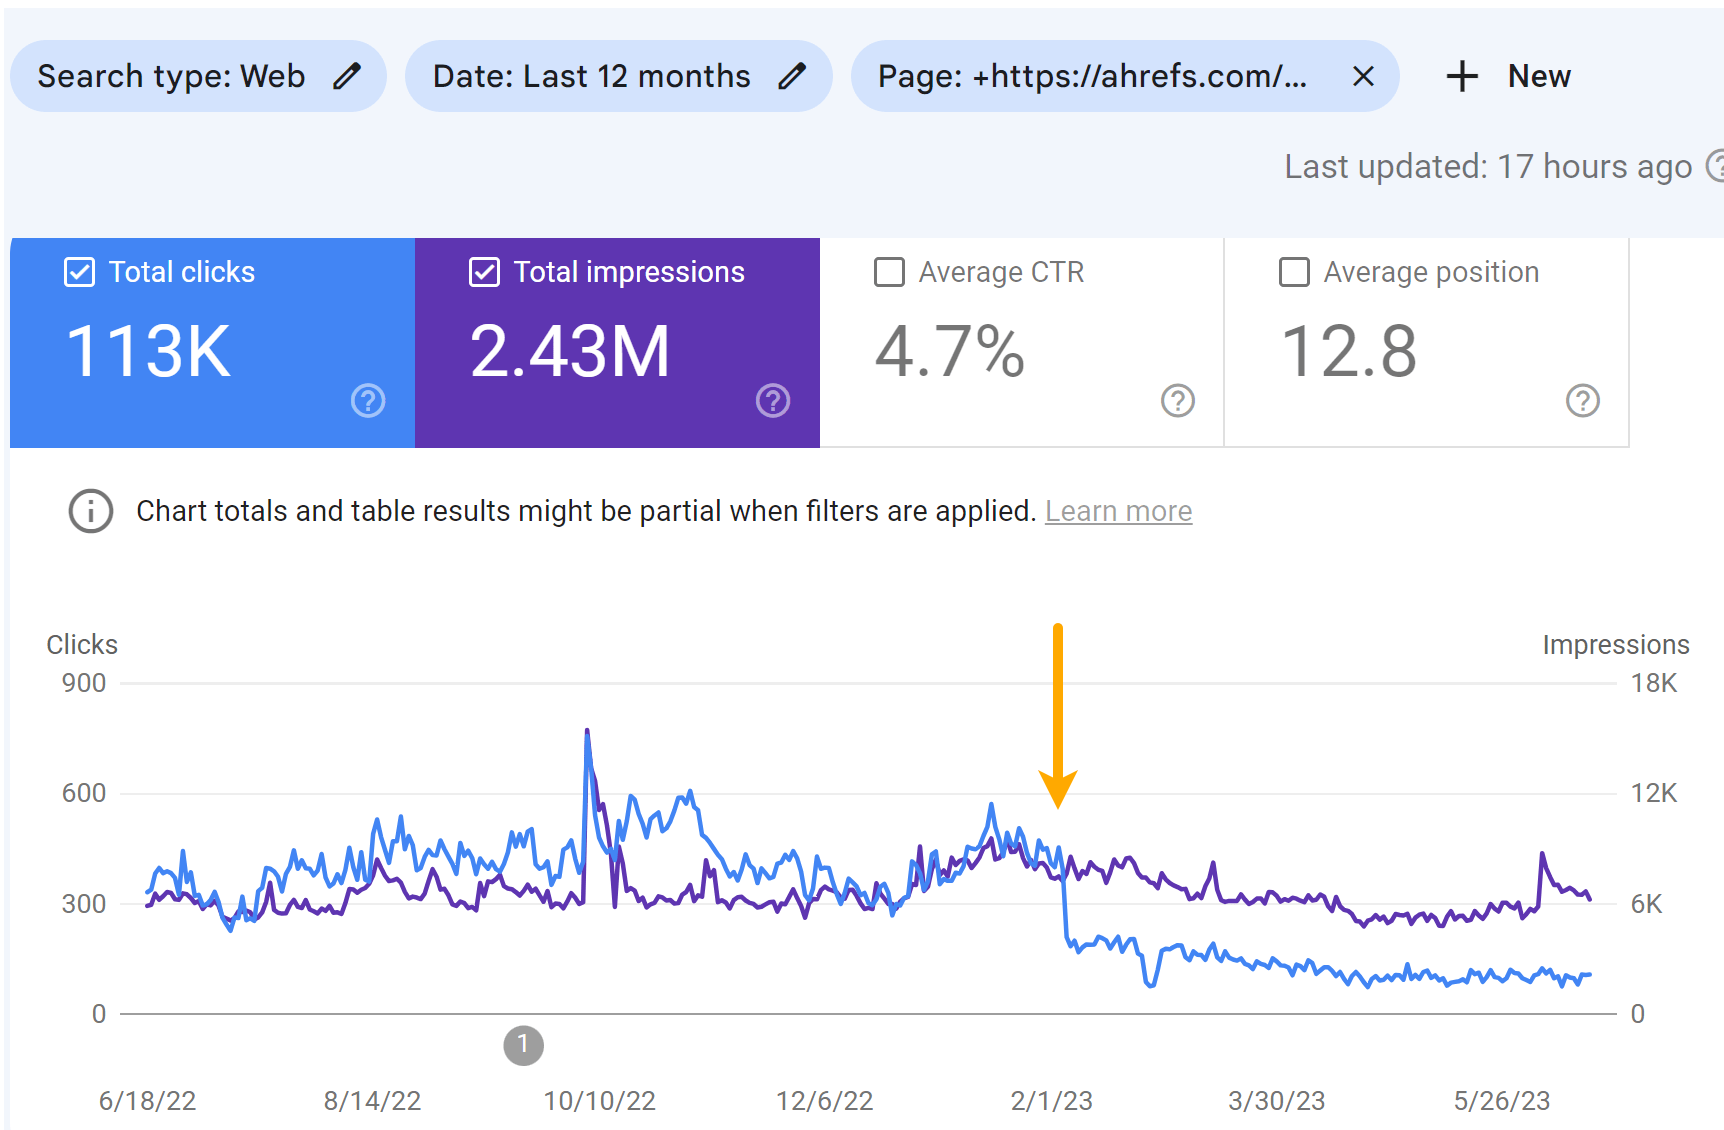
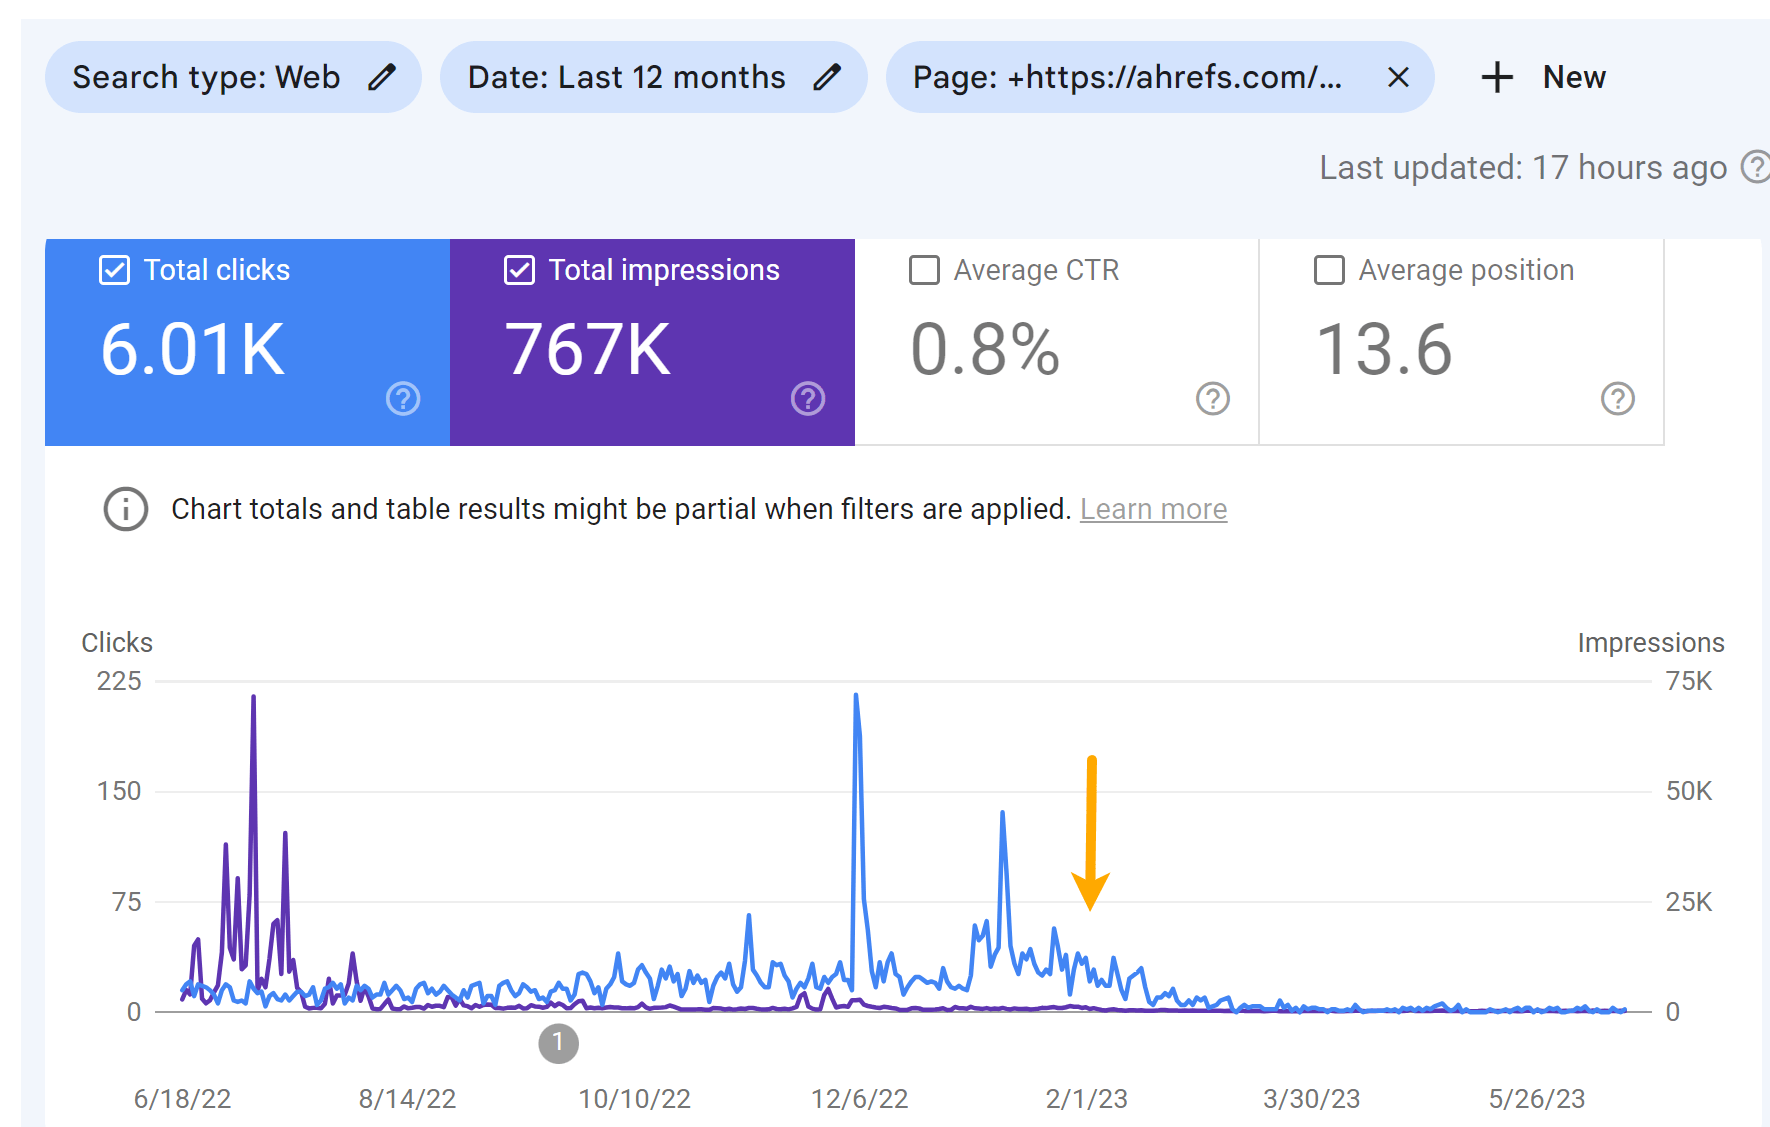
As you’ll be able to see within the charts beneath, each pages misplaced some visitors. However it didn’t lead to a lot change to our visitors estimate like I used to be anticipating.
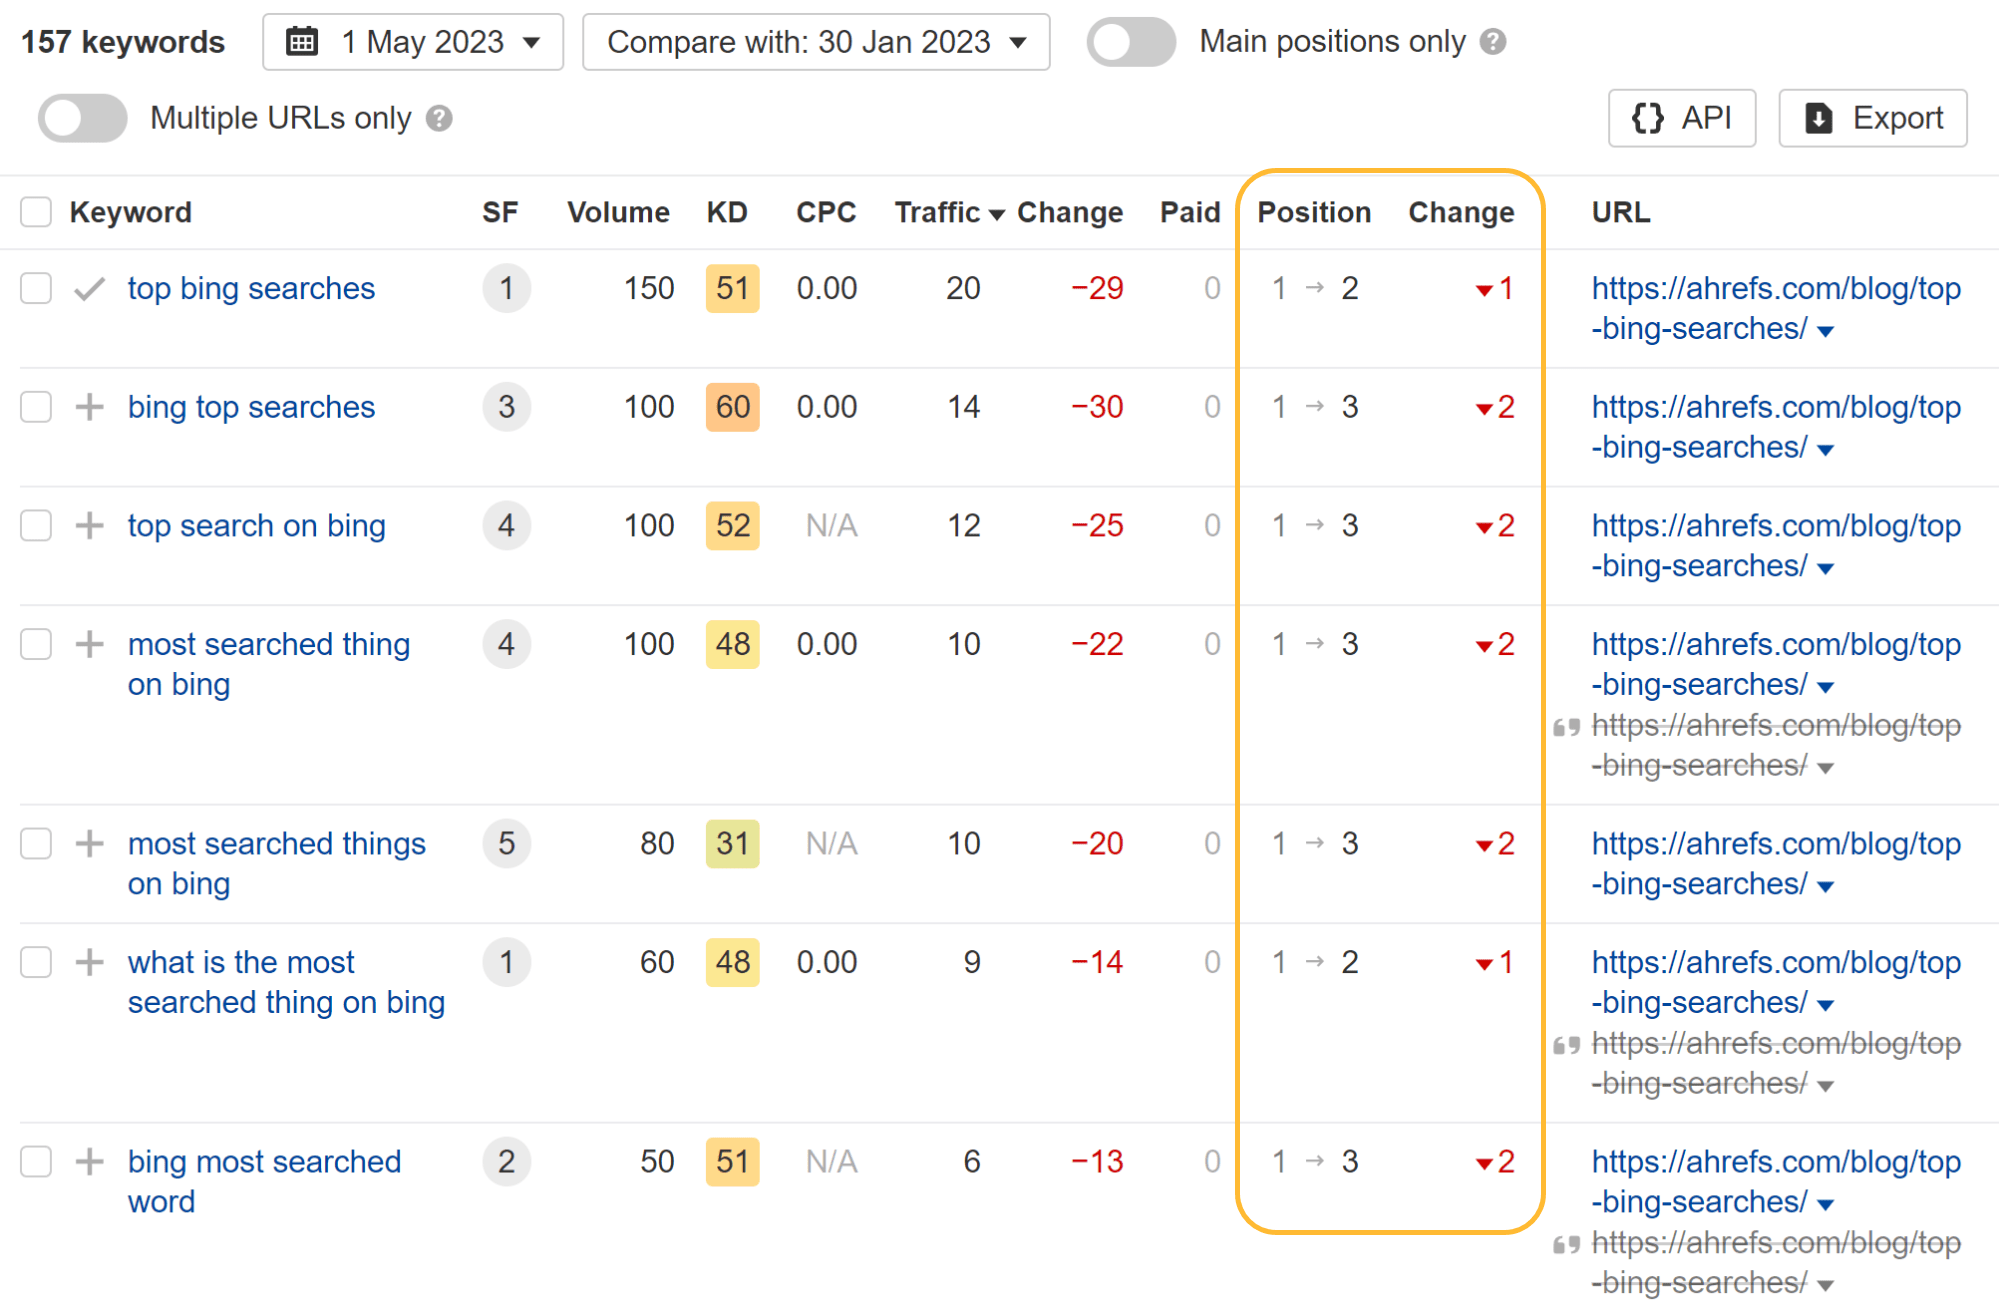
Trying on the particular person key phrases, you’ll be able to see that some key phrases misplaced a place or two and others truly gained rating positions whereas the web page was blocked from crawling.
Essentially the most fascinating factor I seen is that they misplaced all featured snippets. I assume that having the pages blocked from crawling made them ineligible for featured snippets. After I later eliminated the block, the article on Bing searches rapidly regained some snippets.
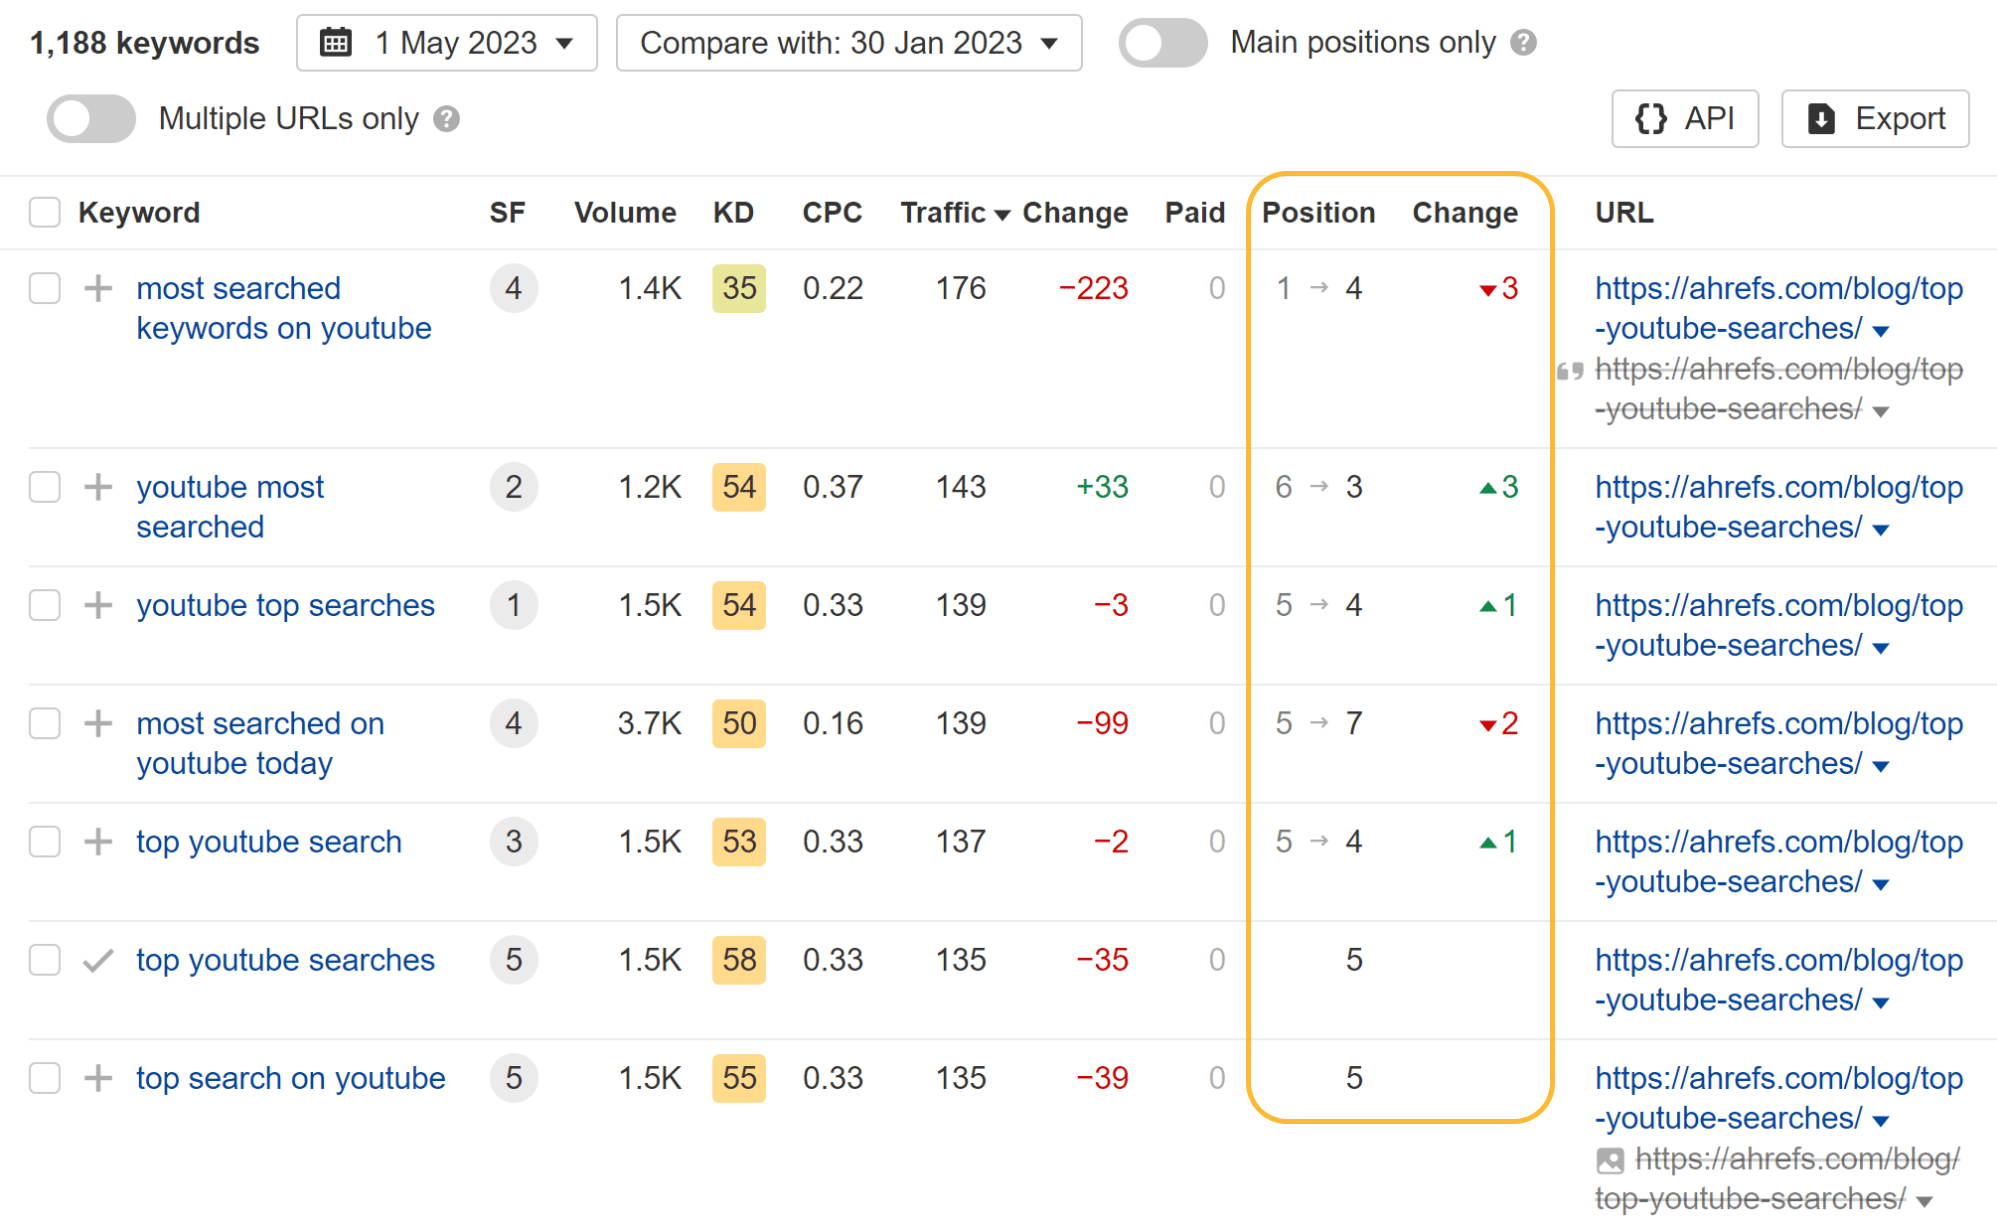
Essentially the most noticeable influence to the pages is on the SERP. The pages misplaced their customized titles and displayed a message saying that no data was accessible as a substitute of the meta description.
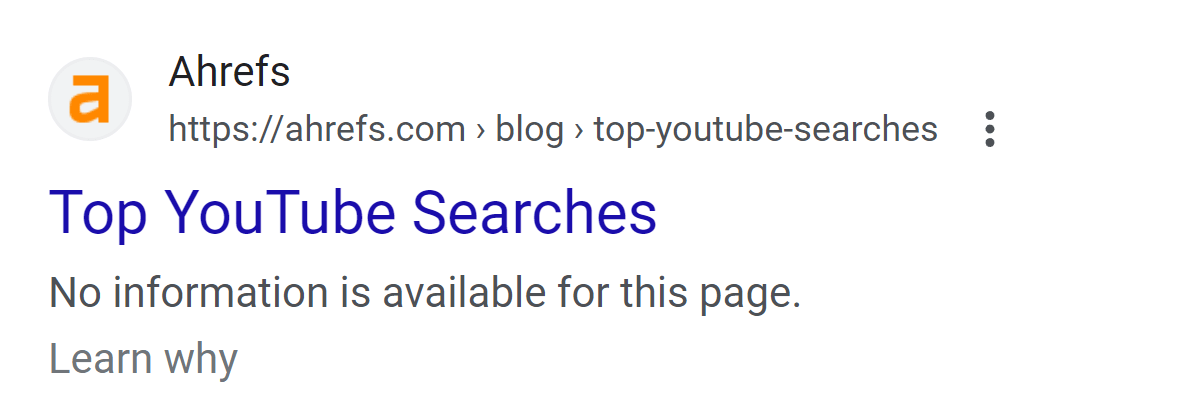
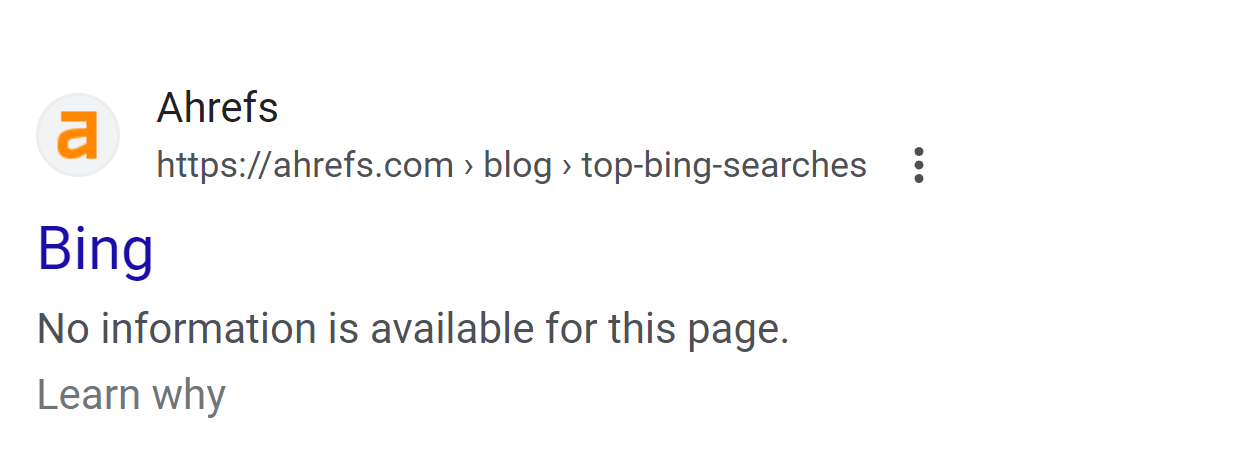
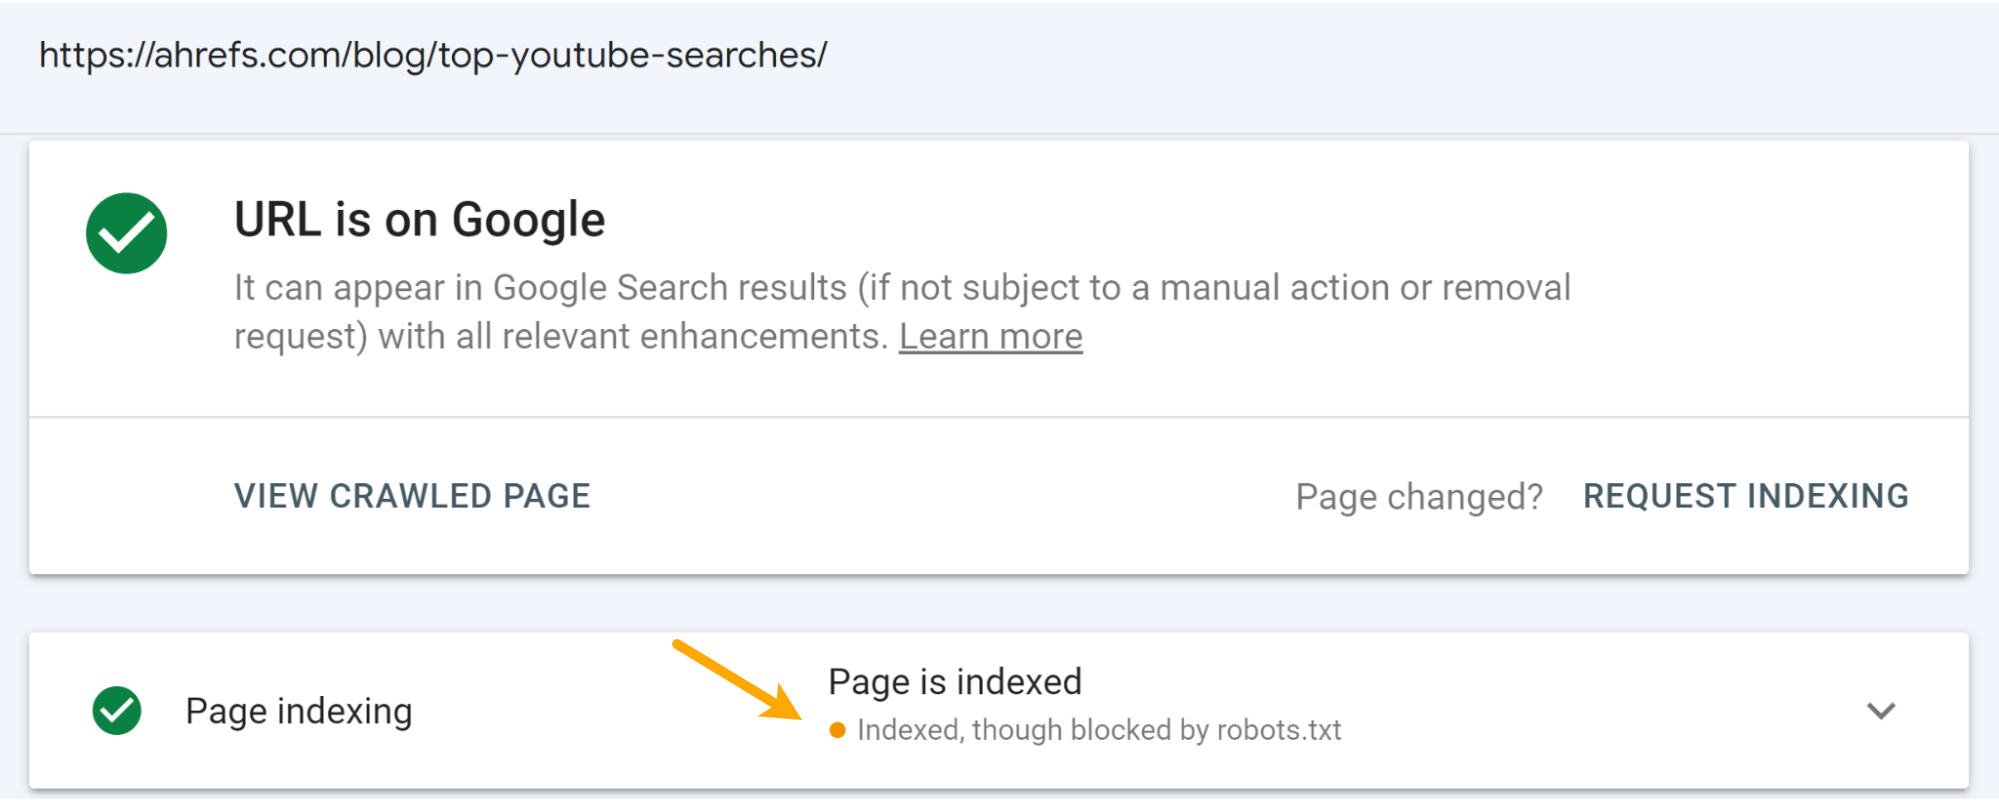
This was anticipated. It occurs when a web page is blocked by robots.txt. Moreover, you’ll see the “Listed, although blocked by robots.txt” standing in Google Search Console for those who examine the URL.
I consider that the message on the SERPs damage the clicks to the pages greater than the rating drops. You’ll be able to see some drop within the impressions, however a bigger drop within the variety of clicks for the articles.
Site visitors for the “Prime YouTube Searches” article:
Site visitors for the “Prime Bing Searches” article:
Last ideas
I don’t suppose any of you’ll be shocked by my commentary on this. Don’t block pages you need listed. It hurts. Not as dangerous as you may suppose it does—nevertheless it nonetheless hurts.

